Subsetting and Indexing
|
This content was generated with the assistance of AI and should be verified against the official documentation before being relied on in production. The reference material consulted while preparing these pages is listed in the section bibliography. |
Checked against R 4.6.1 (2026-06-24) on 2026-10-20; R 4.6.2 is scheduled for 2026-10-29. Everything on this page is base R (base, utils, stats and methods), so no add-on package version applies; the scripts also use the book class of the running shelf scenario, which is plain base R code, and the lintr 3.4.0 default linters were used only to check the scripts. Selecting parts of an object and replacing them is the operation an R program performs most often, and it is where most of the surprises of the language live: the same square bracket returns a vector, a matrix, a list or a data frame depending on what it is applied to and on whether a comma is present; a missing value in a condition adds a row of NA instead of an error; a matrix that has one row left stops being a matrix; and x[[i]] <- NULL deletes while x[i] <- list(NULL) stores. This page goes through the three operators [, [[ and $, the four kinds of index that [ accepts and the special cases of zero, NA and out-of-bounds values, matrices, arrays and index matrices, lists and data frames, the functions that turn conditions into positions (which(), which.max(), head(), tail(), match() and %in%), then sub-assignment with all of its traps, how a replacement call such as names(x)[2] <- "b" is evaluated, and the difference between subset() and [. It ends with the warning that R-devel adds for x[logi] and with a table of every error and warning text that the examples produced.
Every example below is a script that was run with Rscript on R 4.6.1 with warnings printed as they happen (options(warn = 1)), and the lines starting with #> are what it printed. The scripts pass the default lintr linters; where a helper needs an assignment that a default linter dislikes (the <<- inside warns() below) the line carries a # nolint: comment. Errors and warnings that a script shows on purpose are caught, and their real text is printed: msg(expr) returns the text of the error that expr signals, and warns(expr) lets expr finish and returns the text of the warnings it gave, so the messages below are exactly what R says. The examples use the library scenario of the section: books, loans, shelf_today, loan_days and the book class come from the scenario.R file described on the section index, and the scripts that use them start with source("scenario.R"). The outputs are the real outputs of R 4.6.1; the only change is that the trailing blanks that R prints after a printed vector have been removed.
The pages Atomic Vectors and Types, Lists, Data Frames and Matrices and Arrays introduce the objects themselves; this page is about getting parts of them in and out. Names and other attributes are in Attributes and Names, missing values in Missing and Special Values, and the question of when an object is copied after a sub-assignment is in Assignment, Names and Values.
One idea, three operators
R has no separate array, record and dictionary syntax. Everything that holds several values is a vector (atomic or list) with optional attributes, and one family of operators takes parts out of any of them. The language definition lists the forms: x[i], x[i, j], x[[i]], x[[i, j]], x$a and x$"a", and then gives the rules that the rest of this page unfolds: [ can select several elements and returns an object of the same kind, [[ selects exactly one element and returns it, and $ is a shorthand for [[ with a literal name that applies to lists, to NULL and to environments (The R Language Definition: Indexing). The help page puts the first distinction in one sentence: the most important distinction between [, [[ and $ is that [ can select more than one element whereas the other two select a single element (R documentation: Extract).
A way to remember the three is a box of items. [ takes a smaller box with some of the items in it (the result has the type of the container). [[ takes one item out of the box (the result has the type of the item). $ does the same as [[ and saves typing the quotes, at the price of the rules for names that the section on partial matching explains. The figure shows the nine combinations of the three operators and the three most common containers, and the table that follows lists the rules by operator.
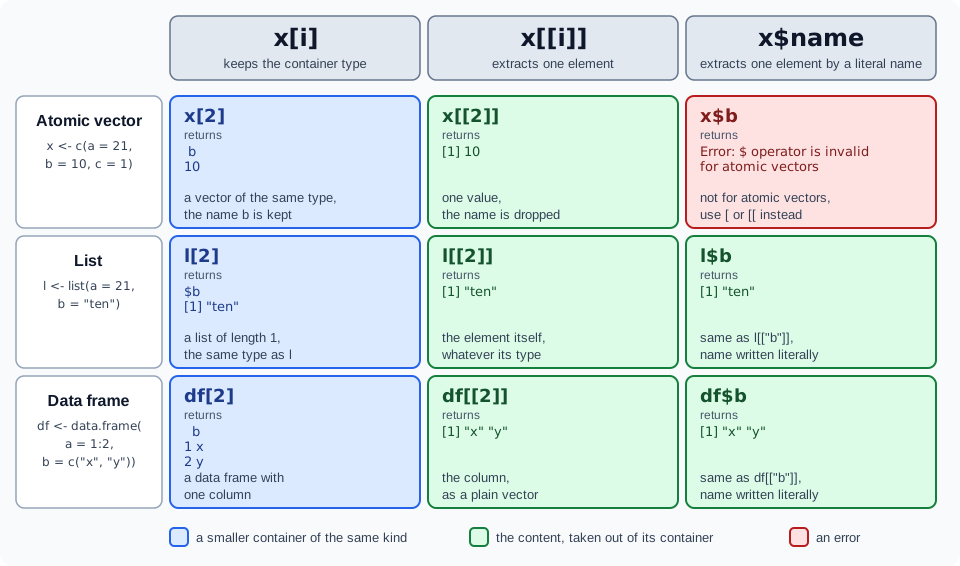
| Rule | [ |
[[ |
$ |
|---|---|---|---|
Elements selected |
any number, by vector index |
exactly one |
exactly one, by a literal name |
Result of the default method |
same kind of container as |
the element itself |
the element itself |
Index types |
positive, negative, logical, character, empty, factor, |
one positive or negative number, one string, a vector for recursive indexing |
a name or a string, never an expression |
Partial matching of names |
never |
only with |
for lists, never for environments |
Out of bounds |
|
error |
|
Applies to atomic vectors |
yes |
yes, one element |
no: error |
Source: R documentation: Extract
All three operators are ordinary generic functions, and a class can supply its own method: [.data.frame and [.factor are the two methods that ship with R (The R Language Definition: Indexing other structures). This page describes the default methods and, from the data frame section on, the data frame method. The classes of the S3 classes and generics page can define their own [ and [[; those methods do not have to follow the rules below, for example for partial matching.
An atomic vector is also what a matrix is, with a dim attribute, so every vector form of indexing works on a matrix with a single index (see Matrices and arrays). The same is true of a data frame, which is a list of columns, so df[j] and df[[j]] index it as a list (see Data frames).
The four kinds of index
An introduction to R lists four kinds of index vector for x[i] on a vector: a logical vector, a vector of positive integers, a vector of negative integers, and a vector of character strings; and says that an indexed expression can also appear on the receiving end of an assignment (An Introduction to R: Index vectors; selecting and modifying subsets of a data set). The language definition adds the special cases: a zero, real numbers, factors, the empty index, NULL and NA (The R Language Definition: Indexing by vectors). The first script works through all of them on a vector made from the shelf scenario: the number of days that each of the first eight loans lasted, with the loan ids as names. A loan lasts return_date - loan_date days, and loan_days (21) is the loan period.
source("scenario.R")

# Loan lengths in days for the first eight loans, named by loan id.
# Unreturned or impossible loans would give NA; here L001 to L008 are complete.
days <- as.integer(loans$return_date - loans$loan_date)
names(days) <- loans$loan_id
loan_len <- days[1:8]
loan_len
#> L001 L002 L003 L004 L005 L006 L007 L008
#>   21   10    1   26   26   17   24   10

# 1. Positive integers select by position, in the order given
loan_len[c(1, 3)]
#> L001 L003
#>   21    1
loan_len[c(3, 1)]
#> L003 L001
#>    1   21
loan_len[8:6]
#> L008 L007 L006
#>   10   24   17

# 2. Negative integers drop positions
loan_len[-1]
#> L002 L003 L004 L005 L006 L007 L008
#>   10    1   26   26   17   24   10
loan_len[-(1:5)]
#> L006 L007 L008
#>   17   24   10
loan_len[-c(1, 8)]
#> L002 L003 L004 L005 L006 L007
#>   10    1   26   26   17   24

# 3. Logical vectors keep the TRUE positions
loan_len > loan_days
#>  L001  L002  L003  L004  L005  L006  L007  L008
#> FALSE FALSE FALSE  TRUE  TRUE FALSE  TRUE FALSE
loan_len[loan_len > loan_days]
#> L004 L005 L007
#>   26   26   24

# 4. Character vectors select by name (exact matching)
loan_len[c("L004", "L002")]
#> L004 L002
#>   26   10
loan_len["L999"]
#> <NA>
#>   NA

# Zero is a no-op: nothing is selected, or nothing is dropped
loan_len[0]
#> named integer(0)
loan_len[c(0, 2)]
#> L002
#>   10
loan_len[c(-1, 0)]
#> L002 L003 L004 L005 L006 L007 L008
#>   10    1   26   26   17   24   10
loan_len[-0]
#> named integer(0)

# A negative index outside the vector is silently ignored, a positive one
# gives NA
loan_len[-20]
#> L001 L002 L003 L004 L005 L006 L007 L008
#>   21   10    1   26   26   17   24   10
loan_len[10]
#> <NA>
#>   NA
loan_len[c(1, 10)]
#> L001 <NA>
#>   21   NA

# Real numbers are truncated toward zero
loan_len[2.9]
#> L002
#>   10
loan_len[-1.9]
#> L002 L003 L004 L005 L006 L007 L008
#>   10    1   26   26   17   24   10
loan_len[0.9]
#> named integer(0)

# Duplicated positive indices repeat the element
loan_len[c(2, 2, 2)]
#> L002 L002 L002
#>   10   10   10

# The empty index and NULL
loan_len[]
#> L001 L002 L003 L004 L005 L006 L007 L008
#>   21   10    1   26   26   17   24   10
loan_len[NULL]
#> named integer(0)The rules the output shows, one by one:
-
A vector of positive integers selects by position, in the order given and as often as given. The result has the length of the index, so
loan_len[c(3, 1)]reverses two elements andloan_len[c(2, 2, 2)]repeats one. The names of the selected elements are selected with them. -
A vector of negative integers selects everything except the positions given. The elements of the index must all have the same sign. A negative position that is outside the vector is silently ignored (
loan_len[-20]returns the whole vector); the language definition says this has been so since R 2.6.0, for compatibility with S, because dropping a non-existent element is an empty operation. -
A logical vector keeps the positions where it is
TRUE.loan_len > loan_daysis a logical vector with the names ofloan_len, so it can be used directly as the index, and this is the form that most filters take:x[condition]. -
A character vector is matched against the names of
x. The match is exact for[: there is no partial matching with a single bracket for any object. A name that is not there givesNAwith the name<NA>. -
Zero is the neutral index.
x[0]is an empty vector of the same type (a named empty vector whenxhas names, printednamed integer(0)), and a zero among positive or negative indices is as if it were not there:x[c(0, 2)]isx[2]andx[c(-1, 0)]isx[-1]. The case ofx[-0]is a trap:-0is0, sox[-0]selects nothing, it does not drop nothing. Code that builds the index as-nwithnpossibly zero (x[-n]) returns an empty vector exactly when it should return all ofx. -
A positive index larger than
length(x)givesNAfor that position, and the result still has the length of the index:loan_len[c(1, 10)]has two elements, the second named<NA>. -
Real numbers are truncated towards zero, so
loan_len[2.9]isloan_len[2]andloan_len[-1.9]isloan_len[-1];loan_len[0.9]isloan_len[0]. R 4.2.0 made the implementation follow what had always been documented: the index isas.integer(i)unless that would overflow, and thentrunc(i)(R NEWS: Changes in R 4.2.0). -
The empty index
x[]returnsx(all of it, with its names,dimanddimnames), andNULLis treated asinteger(0), sox[NULL]is empty. The empty index matters most on the left of an assignment (x[] <- 0keeps the attributes ofx), see Sub-assignment of vectors.
Zero, NA and the length of the index
Three things go wrong in practice with indexes that are not plain vectors of valid positions: mixing signs, missing values in the index and the interplay of logical indexes with recycling. The second script shows them, with the real text of the one error in the group.
source("scenario.R")

days <- as.integer(loans$return_date - loans$loan_date)
names(days) <- loans$loan_id
loan_len <- days[1:8]

# Mixing positive and negative subscripts is an error; zeros are the exception
tryCatch(loan_len[c(-1, 2)], error = \(e) conditionMessage(e))
#> [1] "only 0's may be mixed with negative subscripts"
loan_len[c(-1, 0)]
#> L002 L003 L004 L005 L006 L007 L008
#>   10    1   26   26   17   24   10

# An NA subscript gives NA: the logical NA recycles to the length of x, the
# integer NA selects one element
loan_len[NA]
#> <NA> <NA> <NA> <NA> <NA> <NA> <NA> <NA>
#>   NA   NA   NA   NA   NA   NA   NA   NA
loan_len[c(1, NA)]
#> L001 <NA>
#>   21   NA
loan_len[c(1, NA_integer_)]
#> L001 <NA>
#>   21   NA
loan_len[NA_character_]
#> <NA>
#>   NA

# An NA inside a logical index selects an NA element, so a comparison on data
# that holds a missing value returns an NA entry; which() keeps only the TRUEs
with_gap <- c(a = 21L, b = NA, c = 26L)
with_gap > 21L
#>     a     b     c
#> FALSE    NA  TRUE
with_gap[with_gap > 21L]
#> <NA>    c
#>   NA   26
with_gap[which(with_gap > 21L)]
#>  c
#> 26

# warns() lets expr finish and returns the text of the warnings it gave
warns <- function(expr) {
  seen <- character()
  withCallingHandlers(
    expr,
    warning = \(w) {
      seen <<- c(seen, conditionMessage(w)) # nolint: assignment_linter.
      invokeRestart("muffleWarning")
    }
  )
  seen
}

# A short logical index is recycled, a long one extends x with NA. R 4.6.1
# gives no warning when the length of the index does not divide length(x).
loan_len[c(TRUE, FALSE)]
#> L001 L003 L005 L007
#>   21    1   26   24
loan_len[c(TRUE, FALSE, FALSE)]
#> L001 L004 L007
#>   21   26   24
warns(loan_len[c(TRUE, FALSE, FALSE)])
#> character(0)
length(loan_len[rep(TRUE, 10)])
#> [1] 10
loan_len[rep(c(TRUE, FALSE), length.out = 10)]
#> L001 L003 L005 L007 <NA>
#>   21    1   26   24   NA

# Character subscripts on a vector without names, with unknown names, with "",
# and with duplicated names
plain <- c(21L, 10L, 1L)
plain["a"]
#> [1] NA
loan_len["L99"]
#> <NA>
#>   NA
loan_len[""]
#> <NA>
#>   NA
dup <- c(x = 1, y = 2, x = 3)
dup["x"]
#> x
#> 1
dup[c("x", "x")]
#> x x
#> 1 1

# [ never uses partial matching
loan_len["L00"]
#> <NA>
#>   NA

# A factor subscript uses the integer codes, not the labels
f <- factor(c("L003", "L001"))
as.integer(f)
#> [1] 2 1
loan_len[f]
#> L002 L001
#>   10   21
loan_len[as.character(f)]
#> L003 L001
#> 1 21Mixing positive and negative subscripts
loan_len[c(-1, 2)] is an error. The message of R 4.6.1 is only 0's may be mixed with negative subscripts: zero is the single value that may be combined with negative numbers, because it selects nothing and drops nothing. Some older posts quote the wording can't mix positive and negative subscripts; this is not the text that R 4.6.1 prints, and the NEWS files do not record the change of wording, so search for the message as printed on your version. The reason for the restriction is that "everything except 1, and also the second element" has no meaning: a negative index means "all but these", and a positive one means "only these".
NA in the index
The index can contain NA, and its type decides the result. The language definition explains it with one example: x[NA] has the length of x, whereas x[c(1, NA)] has length 2, because the literal NA is a logical value and the rules for logical indexes apply to it, while in c(1, NA) it is coerced to an integer. The output above shows both:
-
loan_len[NA]recycles the logicalNAto the length of the vector and returns eightNAvalues, all with the name<NA>. -
loan_len[c(1, NA)]returns the first element and oneNA. -
NA_integer_andNA_character_select one unknown element and return oneNA.
The help page generalises this: when extracting, a numeric, logical or character NA index picks an unknown element and returns NA in the corresponding position of a logical, integer, numeric, complex or character result, and NULL for a list (and a raw zero byte for a raw vector). The practical consequence is the one that gets its own section for data frames: a comparison on data that holds a missing value produces an NA in the logical index, and the result of the filter holds an NA element for it. with_gap[with_gap > 21L] in the script returns NA and 26, while with_gap[which(with_gap > 21L)] returns only 26, because which() drops everything that is not TRUE. The fix for a filter on data that may have missing values is one of which(), !is.na(x) & x > 21L or subset(); see Rows by condition and the NA-row trap.
Logical indexes and recycling
A logical index is recycled to the length of the vector if it is shorter, as the manual says, and if it is longer then the vector is conceptually extended with NA values. The script shows the three cases: c(TRUE, FALSE) selects every other element, c(TRUE, FALSE, FALSE) selects positions 1, 4 and 7 of a vector of length eight, and a logical index of length ten applied to a vector of length eight selects two positions that do not exist, which are returned as NA. One more observation belongs to The upcoming R-devel warning for x[logi]: R 4.6.1 gives no warning when the length of the logical index does not divide the length of the vector. The call warns(loan_len[c(TRUE, FALSE, FALSE)]) returns character(0), which means that the expression produced no warning.
Character indexes
A character index is matched against names(x). If x has no names at all, every name is the empty string and nothing matches: plain["a"] is NA, and the result has no name because the vector has none to carry. Four rules are worth remembering:
-
the string
""matches no element, not even those without a name (loan_len[""]isNA); -
NA_character_also matches nothing; -
when names are duplicated, a character index returns the first element with that name, and an index of two equal strings returns that element twice (
dup[c("x", "x")]is1 1); the secondxofdupcan only be reached by position; -
partial matching is never used by
[, soloan_len["L00"]isNAeven though"L00"is a prefix of every name.
The script also shows the fifth kind of index that the manual lists, a factor. A factor index is the same as x[as.integer(f)]: the integer codes are used and the labels are never looked at. The levels of f are sorted, so f <- factor(c("L003", "L001")) has the codes 2 and 1, and loan_len[f] returns the second and the first element, not the elements called L003 and L001. The result is wrong and nothing says so. If the labels are meant, convert them: loan_len[as.character(f)]. This trap was more common when read.csv() and data.frame() made factors from strings by default; since R 4.0.0 the default of stringsAsFactors is FALSE and a character column is indexed by its values (R NEWS: Changes in R 4.0.0). The Factors page has the details on the factors themselves.
Attributes
[ keeps names (and dim and dimnames for arrays) and drops all other attributes; the help page says that this holds for every subsetting except the one with an empty index. Classes that have their own method keep more, as the next script shows: Date and factor keep their class and factor also keeps all its levels, including those that no selected element uses.
source("scenario.R")

msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))

# [ keeps names, dim and dimnames; other attributes are dropped ...
x <- structure(c(a = 1, b = 2, c = 3), unit = "days", note = "demo")
attributes(x)
#> $names
#> [1] "a" "b" "c"
#>
#> $unit
#> [1] "days"
#>
#> $note
#> [1] "demo"
#>
attributes(x[1:2])
#> $names
#> [1] "a" "b"
#>

# ... except where a class has its own method, as Date and factor do
d <- as.Date("2026-06-30") + 0:2
class(d[1:2])
#> [1] "Date"
f <- factor(c("fiction", "poetry", "fiction"))
f[2:3]
#> [1] poetry  fiction
#> Levels: fiction poetry
class(f[2:3])
#> [1] "factor"
levels(f[2])
#> [1] "fiction" "poetry"

# An empty index keeps everything, so x[] <- v changes values and keeps the
# attributes, while x <- v does not
x[] <- 0
attributes(x)
#> $names
#> [1] "a" "b" "c"
#>
#> $unit
#> [1] "days"
#>
#> $note
#> [1] "demo"
#>

# Subscripts of an unsuitable type
msg(x[list(1)])
#> [1] "invalid subscript type 'list'"
msg(x[mean])
#> [1] "invalid subscript type 'closure'"
msg((1:3)[[list(1)]])
#> [1] "invalid subscript type 'list'"
msg(list(1, 2)[[mean]])
#> [1] "invalid subscript type 'closure'"

# Too many or too few subscripts
msg((1:3)[1, 2])
#> [1] "incorrect number of dimensions"
msg((1:3)[[1, 2]])
#> [1] "incorrect number of subscripts"
msg(matrix(1:4, 2)[[1, 2, 3]])
#> [1] "incorrect number of subscripts"
msg(matrix(1:4, 2)[3, 1])
#> [1] "subscript out of bounds"

# Rows beyond the end of a data frame give NA rows with made-up names
books[c(15, 17, 18), c("title", "year")]
#>            title year
#> 15   Ten Winters 2022
#> NA          <NA>   NA
#> NA.1        <NA>   NA
msg(books[, 7])
#> [1] "undefined columns selected"
msg(books[[7]])
#> [1] "subscript out of bounds"

# An empty data frame selection keeps the columns
books[0, c("title", "year")]
#> [1] title year
#> <0 rows> (or 0-length row.names)
books[FALSE, "title"]
#> character(0)
Source: R documentation: Extract
The first two statements show the rule, the next four the exceptions and the empty index: x[] <- 0 changes the values and keeps the unit and note attributes, while x <- 0 would replace the object. The error messages in the second half belong to the table at the end of the page.
Single bracket versus double bracket
[[ selects one element and drops the container. On an atomic vector it also drops the names, which is one of the small semantic differences that the language definition mentions for vectors and matrices: [[ drops any names or dimnames attribute, and it can use partial matching of character indexes when exact = FALSE. On a list it is the form that you use to take out one element, whereas [ returns a list of the selected elements.
source("scenario.R")

days <- as.integer(loans$return_date - loans$loan_date)
names(days) <- loans$loan_id
loan_len <- days[1:8]

# msg() returns the text of the error that evaluating expr signals
msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))

# On an atomic vector [ keeps the names, [[ drops them and returns one value
loan_len[2]
#> L002
#>   10
loan_len[[2]]
#> [1] 10
loan_len["L002"]
#> L002
#>   10
loan_len[["L002"]]
#> [1] 10

# [[ takes exactly one element
msg(loan_len[[1:2]])
#> [1] "attempt to select more than one element in vectorIndex"
msg(loan_len[[c(TRUE, FALSE)]])
#> [1] "attempt to select more than one element in vectorIndex"
msg(loan_len[[0]])
#> [1] "attempt to select less than one element in get1index <real>"
msg(loan_len[[NULL]])
#> [1] "attempt to select less than one element in get1index"
msg(loan_len[[]])
#> [1] "missing subscript"

# Out of bounds: [ pads with NA, [[ is an error
loan_len[10]
#> <NA>
#>   NA
msg(loan_len[[10]])
#> [1] "subscript out of bounds"
msg(loan_len[["L99"]])
#> [1] "subscript out of bounds"
msg(loan_len[[-1]])
#> [1] "invalid negative subscript in get1index <real>"
msg(loan_len[[NA]])
#> [1] "subscript out of bounds"
msg(loan_len[[Inf]])
#> [1] "subscript out of bounds"

# Negative subscripts work in [[ only when exactly one element is left
msg((1:2)[[-1]])
#> [1] 2
msg((1:3)[[-1]])
#> [1] "invalid negative subscript in get1index <real>"

# The out-of-bounds error is classed; it holds the object and the index
err <- tryCatch(loan_len[[10]], error = identity)
class(err)
#> [1] "subscriptOutOfBoundsError" "error"
#> [3] "condition"
identical(err$object, loan_len)
#> [1] TRUE
err$index
#> [1] 10

# An object that cannot be subset
msg(mean[1])
#> [1] "object of type 'closure' is not subsettable"
err <- tryCatch(mean[1], error = identity)
class(err)
#> [1] "notSubsettableError" "error"               "condition"

# [[ with a name matches exactly by default
msg(loan_len[["L00"]])
#> [1] "subscript out of bounds"
Source: R documentation: Extract
The script shows the contrast and the messages of the errors:
-
loan_len[2]andloan_len["L002"]return a named vector,loan_len[[2]]andloan_len[["L002"]]return the bare value 10. -
[[requires exactly one element. A vector of length two givesattempt to select more than one element in vectorIndex; a zero,NULLor a missing index givesattempt to select less than one element in get1index <real>, the same text without<real>forNULL, ormissing subscriptforx[[]]. R 4.3.0 turnedc(a = 1, 2)[[]]from "matches the second element" into a classed error and madeNULL[[]]an error too (R NEWS: Changes in R 4.3.0); the help page says thatx[[]]is always an error. -
Out of bounds.
loan_len[10]isNA,loan_len[[10]]is the errorsubscript out of bounds, and so is an unknown name (loan_len[["L99"]]), anNAindex on an atomic vector and an infinite one (loan_len[[Inf]]). R 4.0.0 removed the undefined behaviour ofx[[Inf]](which isNULLfor a list) and madex[[-Inf]]andx[[-n]]give more helpful messages (R NEWS: Changes in R 4.0.0). -
Negative numbers are allowed in
[[only when exactly one element is left.(1:2)[[-1]]is 2, whileloan_len[[-1]]isinvalid negative subscript in get1index <real>. -
The error of an out-of-bounds subscript has the class
subscriptOutOfBoundsErrorand the error for an object that cannot be subset has the classnotSubsettableError, with the object in theobjectfield of the condition. R 4.2.0 introduced both classes, so that a handler can tell them from other errors without matching the text. Formean[1], the message isobject of type 'closure' is not subsettable. Thesubscriptfield of the error isNAfor the vector case in R 4.6.1 and theindexfield holds the erroneous index, while the help page says thatsubscriptis zero for vector subscripting; useindexandobjectand treatsubscriptwith care.
For lists the rules for missing things are different from the ones for atomic vectors, and this is a very common source of silent errors: a name that does not exist gives NULL with [[ and $ on a list, an error with [[ on an atomic vector, and NA with [. The help page says that attempting to extract a non-existent element by name returns NULL, and an out-of-bounds position on a list is an error (reading_list[[4]] below).
The dollar operator and partial matching
$ is the operator of records: book$title is the title of a book of the scenario. It is documented for lists, for pairlists and for NULL, and for environments; the language definition adds that the index is not computable (when the index has to be computed, use x[[expr]]) and that applying $ to a non-recursive object is an error. The help page defines it by its equivalent: x$name is equivalent to x[["name", exact = FALSE]].
source("scenario.R")

msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))
wmsg <- \(expr) tryCatch(expr, warning = \(w) conditionMessage(w))

# A book from the scenario is a list with class "book"; $ takes a name
dune <- book("Dune", author = "Frank Herbert", year = 1965, pages = 412)
dune$title
#> [1] "Dune"
dune$pages
#> [1] 412
dune[["author"]]
#> [1] "Frank Herbert"
unclass(dune)$year
#> [1] 1965

# A name that does not exist gives NULL, not an error
dune$publisher
#> NULL
dune[["publisher"]]
#> NULL
is.null(dune$publisher)
#> [1] TRUE

# $ also accepts a unique prefix of a name, and nothing warns by default
dune$tit
#> [1] "Dune"
dune$p
#> [1] 412

# An ambiguous prefix matches nothing, so the result is NULL
shelf_entry <- list(pages = 412L, pagesize = "A5")
shelf_entry$pa
#> NULL
shelf_entry$pages
#> [1] 412
shelf_entry$pagesize
#> [1] "A5"

# [[ matches exactly unless exact is changed
shelf_entry[["pag"]]
#> NULL
shelf_entry[["pagesi"]]
#> NULL
shelf_entry[["pagesi", exact = FALSE]]
#> [1] "A5"
wmsg(shelf_entry[["pagesi", exact = NA]])
#> [1] "partial match of 'pagesi' to 'pagesize'"
shelf_entry[["pagesi", exact = TRUE]]
#> NULL

# The option that makes partial matching on $ loud
old <- options(warnPartialMatchDollar = TRUE)
wmsg(shelf_entry$pagesi)
#> [1] "partial match of 'pagesi' to 'pagesize'"
wmsg(dune$tit)
#> [1] "partial match of 'tit' to 'title'"
options(old)
getOption("warnPartialMatchDollar")
#> [1] FALSE

# [ never matches partially, for any container
shelf_entry["pagesi"]
#> $<NA>
#> NULL
#>
names(shelf_entry["pagesi"])
#> [1] NA

# $ cannot be computed; use [[ for a name held in a variable
field <- "title"
dune$field
#> NULL
dune[[field]]
#> [1] "Dune"
msg(dune$"title")
#> [1] "Dune"

# $ on an atomic vector is an error, on NULL it is NULL
loan_len <- c(L001 = 21L, L002 = 10L)
msg(loan_len$L001)
#> [1] "$ operator is invalid for atomic vectors"
NULL$a
#> NULL

# getElement() is [[ with exact matching that also reads S4 slots
getElement(dune, "title")
#> [1] "Dune"
getElement(shelf_entry, "pag")
#> NULL

# Environments: $ and [[ look up a name, exactly
shelf_env <- new.env()
shelf_env$open <- TRUE
shelf_env$open
#> [1] TRUE
shelf_env[["op"]]
#> NULL
shelf_env$op
#> NULL
Source: R documentation: Extract
What the output shows:
-
A unique prefix is accepted.
dune$titis the title anddune$pis the number of pages, because onlypagesbegins withp. Nothing warns by default. When several names have the prefix, aspagesandpagesizehavepa, the match fails and the result isNULL: an ambiguous prefix is not an error either. -
[[does not match partially by default. The usage of the help page isx[[i, exact = TRUE]]and the behaviour of R 4.6.1 agrees:shelf_entry[["pagesi"]]isNULL. The argumentexacthas three values:TRUE(no partial matching, the default),NA(partial matching with a warning) andFALSE(partial matching without warning). The warning has the textpartial match of 'pagesi' to 'pagesize'. The language definition says in its section on indexing by vectors that the default ofexactisNA; that sentence is out of date, the help page and the behaviour are the reference. -
options(warnPartialMatchDollar = TRUE)makes$warn with the same text whenever it matches a prefix. The option isFALSEunless you set it (the options page describes it as a logical switch that warns when partial matching is used for extraction by$). The warning for data frames was given by default in R versions before 3.1.1, whose NEWS says it is now only given when this option isTRUE. A package that wants to be sure that no code relies on a partial match can turn the option on in its tests (see Testing with testthat); the help page example uses it to checkli$p. -
[never matches partially, for any object:shelf_entry["pagesi"]is a list with oneNULLelement named<NA>. -
$cannot be computed.dune$fieldlooks for an element called"field"(and returnsNULL), whereasdune[[field]]uses the value of the variable.dune$"title"works because a string is allowed as the name. -
$on an atomic vector is an error with the text$ operator is invalid for atomic vectors, and$onNULLreturnsNULL. The error is the usual sign of a vector that should have been a list or data frame, for example a column of a data frame (a vector) on which$was used again. -
getElement(x, name)isx[[name, exact = TRUE]], and for S4 objects it reads the slot, so it works on both kinds of object. -
For environments,
$and[[take a character name and do an exact lookup withget(i, envir = x, inherits = FALSE); they returnNULLwhen there is no match, and no partial matching is done.shelf_env$opisNULLalthoughshelf_env$openexists. The replacement forms create or change a binding (see Scoping, Environments and Closures).
The advice that follows from the rules is to use the full names with $, to use [[ with a variable holding a name, and to remember that partial matching exists when a result that should have been a vector is NULL.
The at operator for S4 slots
@ is the fourth extraction operator and applies to S4 objects only, where it reads a slot (R documentation: slotOp). It is the S4 counterpart of $: x@name reads the slot name, x@name <- value replaces it after checking the class of the value, and slot(x, "name") is the function form that accepts a computed name. The next script defines a small S4 class and shows the three error messages. The full treatment of S4 is on S4 Classes and Methods.
msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))

# An S4 class for a book: slots are read with @ and written with @<-
setClass("Book4", slots = c(title = "character", pages = "integer"))
b4 <- new("Book4", title = "Dune", pages = 412L)
b4@title
#> [1] "Dune"
b4@pages
#> [1] 412
slotNames("Book4")
#> [1] "title" "pages"
slot(b4, "pages")
#> [1] 412

# Assigning to a slot checks the class of the value
b4@pages <- 400L
b4@pages
#> [1] 400
msg({
  b4@pages <- "many"
})
#> [1] "assignment of an object of class “character” is not valid for @‘pages’ in an object of class “Book4”; is(value, \"integer\") is not TRUE"

# A slot that does not exist is an error
msg(b4@publisher)
#> [1] "no slot of name \"publisher\" for this object of class \"Book4\""

# $ and [[ do not read slots of an S4 object
msg(b4$title)
#> [1] "$ operator not defined for this S4 class"
msg(b4[["title"]])
#> [1] "this S4 class is not subsettable"

# getElement() is the generic way: it reads a slot for an S4 object
getElement(b4, "title")
#> [1] "Dune"
Source: R documentation: slot
The messages are: for a wrong class of value in an assignment assignment of an object of class “character” is not valid for @‘pages’ in an object of class “Book4”; is(value, "integer") is not TRUE; for a slot that does not exist no slot of name "publisher" for this object of class "Book4"; and for the other two operators on an S4 object $ operator not defined for this S4 class and this S4 class is not subsettable. The quotation marks in the first message are the typographic ones that R printed in this UTF-8 session. getElement(b4, "title") works on both kinds of object because, as the help page says, it returns slot(x, name) for a formally classed object.
Matrices and arrays
A matrix is a vector with a dim attribute and an array is the same with more dimensions, so every kind of vector indexing works with a single index, and there are three more forms for several: one index per dimension, an index matrix, and (as a special case) the logical matrix. The rules for a matrix m[i, j] are those for a vector applied to each dimension, with dimnames taking the place of names (The R Language Definition: Indexing matrices and arrays; An Introduction to R: Array indexing. Subsections of an array).
The examples use a matrix made from the shelf: the page counts of the first twelve books laid out as three shelves (A, B, C) of four slots each. Book 6 (A Map of Salt) has no page count in the scenario, so one cell is NA. The dimnames are named (shelf and slot), which is what makes the header lines of the printed matrices.
source("scenario.R")

msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))

# Page counts of the first twelve books laid out on three shelves of four
# slots. Book 6 has no page count, so one cell is NA.
pages_grid <- matrix(
  books$pages[1:12],
  nrow = 3, byrow = TRUE,
  dimnames = list(shelf = c("A", "B", "C"), slot = c("s1", "s2", "s3", "s4"))
)
pages_grid
#>      slot
#> shelf  s1  s2  s3  s4
#>     A 387 432 214 198
#>     B 301  NA  96 280
#>     C 352 256  88 410

# m[i, j]: one element, a row, a column, several rows and columns
pages_grid[2, 3]
#> [1] 96
pages_grid[2, ]
#>  s1  s2  s3  s4
#> 301  NA  96 280
pages_grid[, "s2"]
#>   A   B   C
#> 432  NA 256
pages_grid[c("A", "C"), c("s1", "s4")]
#>      slot
#> shelf  s1  s4
#>     A 387 198
#>     C 352 410
pages_grid[-1, -(2:3)]
#>      slot
#> shelf  s1  s4
#>     B 301 280
#>     C 352 410

# Rows and columns by condition
pages_grid[, colSums(pages_grid, na.rm = TRUE) > 700]
#>      slot
#> shelf  s1  s4
#>     A 387 198
#>     B 301 280
#>     C 352 410
pages_grid[pages_grid[, "s1"] > 350, ]
#>      slot
#> shelf  s1  s2  s3  s4
#>     A 387 432 214 198
#>     C 352 256  88 410

# One subscript treats the matrix as the vector of its columns, filled down
pages_grid[5]
#> [1] NA
pages_grid[c(1, 12)]
#> [1] 387 410
pages_grid["A"]
#> [1] NA

# A single row or column loses its dimension: the result is a vector
class(pages_grid[1, ])
#> [1] "integer"
dim(pages_grid[1, ])
#> NULL
pages_grid[1, , drop = FALSE]
#>      slot
#> shelf  s1  s2  s3  s4
#>     A 387 432 214 198
dim(pages_grid[, 2, drop = FALSE])
#> [1] 3 1

# Out of bounds is an error for matrices, even with [
msg(pages_grid[4, 1])
#> [1] "subscript out of bounds"
msg(pages_grid[, "s9"])
#> [1] "subscript out of bounds"
msg(pages_grid[1, 2, 3])
#> [1] "incorrect number of dimensions"-
With two indexes,
m[i, j], each one is a vector index of any of the kinds above (positive, negative, logical or character, matched against thedimnames), and an empty index (m[2, ],m[, "s2"]) selects the whole extent of that dimension. A comma is what separates a matrix from a vector:m[1, ]is the first row,m[1]is the first value. -
With one index, the
dimanddimnamesare ignored and the matrix is the vector of its values in column-major order and the result is that ofc(m)[i]; the manual warns thatm[1]is usually very different fromm[1, ]orm[, 1].pages_grid[5]is the fifth value, counted down the columns, which is theNAof book 6;pages_grid["A"]isNAbecause a one-index character is matched againstnames, and a matrix has none. -
Out of bounds on a matrix is an error even for
[:pages_grid[4, 1]andpages_grid[, "s9"]aresubscript out of bounds, and the wrong number of indices isincorrect number of dimensions. A vector, in contrast, pads withNA. -
The result of selecting a single row or column has no dimensions: it is a vector (
class(pages_grid[1, ])is"integer",dim(...)isNULL), and it keeps the names that come from the other dimension. This is the subject of the next section.
Why do my matrices lose dimensions: drop = FALSE
When a subscripting operation leaves a dimension of length one, R removes it by default: row <- mat[2, ] is a vector, and an array of dimensions 2 x 3 x 1 x 4 becomes 2 x 3 x 4. The R FAQ says that the behaviour was kept after much discussion as a feature, and advises using drop = FALSE defensively when programming (R FAQ 7.5: Why do my matrices lose dimensions?). The argument is an additional argument to [, it does not count as an index (the manual: m[1, , drop = FALSE] is the first row as a 1 by n matrix) and it must be named. The same applies to a one-dimensional array: any subsetting gives a vector unless drop = FALSE is used.
The trap is in code that works for the usual size of the input and fails on the edge. The next script defines a helper that selects the rows asked for, and calls it with two shelves and with one.
source("scenario.R")

msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))

pages_grid <- matrix(
  books$pages[1:12],
  nrow = 3, byrow = TRUE,
  dimnames = list(shelf = c("A", "B", "C"), slot = c("s1", "s2", "s3", "s4"))
)

# The drop trap: a helper that returns "the rows asked for" works for two rows
# and silently changes type for one
rows_for <- function(m, wanted) {
  m[wanted, ]
}
dim(rows_for(pages_grid, c("A", "B")))
#> [1] 2 4
dim(rows_for(pages_grid, "A"))
#> NULL
rows_for(pages_grid, "A")
#>  s1  s2  s3  s4
#> 387 432 214 198

# The defensive form keeps the matrix whatever the length of wanted
rows_for <- function(m, wanted) {
  m[wanted, , drop = FALSE]
}
dim(rows_for(pages_grid, "A"))
#> [1] 1 4

# An index matrix: one row per element wanted, one column per dimension
pick <- cbind(c(1, 2, 3), c(4, 3, 1))
pick
#>      [,1] [,2]
#> [1,]    1    4
#> [2,]    2    3
#> [3,]    3    1
pages_grid[pick]
#> [1] 198  96 352

# The same with names, as a character matrix matched against the dimnames
pick_names <- cbind(c("A", "B", "C"), c("s4", "s3", "s1"))
pages_grid[pick_names]
#> [1] 198  96 352

# which(arr.ind = TRUE) goes the other way: from a condition to an index matrix
long_ones <- which(pages_grid > 380, arr.ind = TRUE)
long_ones
#>   shelf slot
#> A     1    1
#> A     1    2
#> C     3    4
pages_grid[long_ones]
#> [1] 387 432 410
capped <- pages_grid
capped[long_ones] <- 380L
capped
#>      slot
#> shelf  s1  s2  s3  s4
#>     A 380 380 214 198
#>     B 301  NA  96 280
#>     C 352 256  88 380

# NA and zero rows in an index matrix; negative numbers are not allowed
pages_grid[rbind(c(1, 1), c(0, 0), c(NA, 2))]
#> [1] 387  NA
msg(pages_grid[rbind(c(1, -1))])
#> [1] "negative values are not allowed in a matrix subscript"
msg(pages_grid[cbind("A", "s9")])
#> [1] "subscript out of bounds"
msg(pages_grid[cbind("", "s1")])
#> [1] "subscript out of bounds"

# A logical matrix selects like a logical vector: the result is a vector
pages_grid > 300
#>      slot
#> shelf   s1    s2    s3    s4
#>     A TRUE  TRUE FALSE FALSE
#>     B TRUE    NA FALSE FALSE
#>     C TRUE FALSE FALSE  TRUE
pages_grid[pages_grid > 300]
#> [1] 387 301 352 432  NA 410
pages_grid[which(pages_grid > 300)]
#> [1] 387 301 352 432 410

# The NA cell is selected as NA by the logical test; removing it takes
# a second condition
pages_grid[pages_grid > 300 & !is.na(pages_grid)]
#> [1] 387 301 352 432 410

# upper.tri() and lower.tri() give logical matrices
sq <- pages_grid[, 1:3]
sq
#>      slot
#> shelf  s1  s2  s3
#>     A 387 432 214
#>     B 301  NA  96
#>     C 352 256  88
upper.tri(sq)
#>       [,1]  [,2]  [,3]
#> [1,] FALSE  TRUE  TRUE
#> [2,] FALSE FALSE  TRUE
#> [3,] FALSE FALSE FALSE
sq[upper.tri(sq)]
#> [1] 432 214  96
sq[lower.tri(sq, diag = TRUE)]
#> [1] 387 301 352  NA 256  88
diag(sq)
#> [1] 387  NA  88

# Rows and columns by position: row() and col() give the indices
sq[row(sq) == col(sq) + 1]
#> [1] 301 256dim(rows_for(pages_grid, "A")) is NULL: the result is a vector and anything downstream that expects a matrix (nrow(), apply() over the rows, %*%) fails or does something else. The second definition, with , drop = FALSE, returns a 1 x 4 matrix for one shelf and a 2 x 4 matrix for two, which is the type that the rest of the function can rely on. The same defence applies to data frames (see Data frames), where the default for a single column is also to drop.
Index matrices, logical matrices and the triangles
A third form of indexing a matrix uses a matrix as the single index: a matrix with one column per dimension of x, where each row selects one element and the result is a vector of the length of the number of rows (An Introduction to R: Index matrices). pick <- cbind(c(1, 2, 3), c(4, 3, 1)) selects [1, 4], [2, 3] and [3, 1], the elements that are on a diagonal of the layout, in one operation.
The rules, from the help page and the manual:
-
the index matrix has one column per dimension and one row per element wanted;
-
negative values are not allowed (
negative values are not allowed in a matrix subscript); -
rows with a zero are ignored and rows with
NAgiveNA(pages_grid[rbind(c(1, 1), c(0, 0), c(NA, 2))]has two elements: the value at[1, 1]andNA); -
a character matrix with one column per dimension is matched against the
dimnameswhen the array has them; each row selects one element,NAgivesNA, and an unmatched value or the empty string""is an error (subscript out of bounds). R 4.1.3 changed the case of an array withoutdimnames, where a character matrix of the right shape used to return meaningless results and is now an error; -
assignment works the same way:
capped[long_ones] <- 380Lreplaces the elements at the listed positions, which is the second use in the manual’s example.
An Introduction to R says that an index matrix must be numeric and that any other form of matrix, such as a logical or a character one, is treated as an indexing vector. For logical matrices that is still right and it is the next case; for character matrices the help page of [ documents the matching against the dimnames that the script shows, so the sentence of the introduction is older than the help page.
A logical matrix of the same shape as x is a vector of the same length when used as a single index: pages_grid[pages_grid > 300] returns the values for which the comparison is TRUE, as a vector in column order, and the cell with NA is returned as NA because the logical index is NA there. which(pages_grid > 300) drops it. The comparison keeps the dim and dimnames of the matrix, so pages_grid > 300 prints as a matrix with the shelf and slot labels.
which(x, arr.ind = TRUE) goes the other way, from a condition to an index matrix: the result is a matrix with one row per element, the row names are taken from the first dimension names, and its column names come from names(dimnames(x)) when they exist (shelf and slot above, and row and col otherwise). It can be fed back as an index, which is what pages_grid[long_ones] does. arrayInd() is the function that converts positions to an index matrix for a given dim.
upper.tri() and lower.tri() return logical matrices that mark the elements above or below the diagonal (with diag = TRUE they include it), so sq[upper.tri(sq)] extracts the upper triangle as a vector, in column order. diag(sq) is the diagonal. row(sq) and col(sq) return the row and the column number of each element as matrices of the same shape, and a condition on them, such as row(sq) == col(sq) + 1, selects the sub-diagonal or any other band (R documentation: lower.tri; R documentation: row).
Subsetting a data frame with a logical or two-column integer matrix is possible, but the help page of [.data.frame advises against it: the data frame is first coerced to a matrix, so every column takes the type of the common one. The data frame section shows the replacement form that is useful.
Arrays
An array has one index per dimension; an empty index keeps the whole extent, and the rules of drop apply to each dimension that is left with length one. The array in the next script holds the copy numbers 1 to 24 of the books, in three shelves, four slots and two rooms, so the value of an element tells you where it is: R stores the first dimension fastest, so the copy number is shelf + 3 * (slot - 1) + 12 * (room - 1).
# Copy numbers 1 to 24 stored in a 3 x 4 x 2 array: 3 shelves, 4 slots per
# shelf and 2 rooms. R fills the first dimension fastest, so copy number
# k = shelf + 3 * (slot - 1) + 12 * (room - 1).
msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))

copies <- array(
  1:24,
  dim = c(3, 4, 2),
  dimnames = list(
    shelf = c("A", "B", "C"),
    slot = c("s1", "s2", "s3", "s4"),
    room = c("main", "annex")
  )
)
dim(copies)
#> [1] 3 4 2

# One index per dimension; an empty index keeps the whole dimension
copies[2, 3, 1]
#> [1] 8
copies[, , 1]
#>      slot
#> shelf s1 s2 s3 s4
#>     A  1  4  7 10
#>     B  2  5  8 11
#>     C  3  6  9 12
copies["A", , ]
#>     room
#> slot main annex
#>   s1    1    13
#>   s2    4    16
#>   s3    7    19
#>   s4   10    22
copies[, "s2", "annex"]
#>  A  B  C
#> 16 17 18

# Slices lose the dimensions of length one; drop = FALSE keeps them
dim(copies[, , 1])
#> [1] 3 4
dim(copies[, , 1, drop = FALSE])
#> [1] 3 4 1
dim(copies[1, , , drop = FALSE])
#> [1] 1 4 2
dim(copies[1, 1, , drop = FALSE])
#> [1] 1 1 2

# Fewer indices than dimensions is an error; a single index works on the
# data vector and ignores the dimensions
msg(copies[1, 2])
#> [1] "incorrect number of dimensions"
copies[10]
#> [1] 10
copies[c(TRUE, FALSE, FALSE, FALSE)]
#> [1]  1  5  9 13 17 21

# slice.index() gives the position along one dimension, as row() and col() do
copies[slice.index(copies, 3) == 2][1:4]
#> [1] 13 14 15 16
sum(copies[, , "annex"])
#> [1] 222

# Index matrices work in any number of dimensions: one column per dimension
copies[rbind(c(1, 1, 1), c(3, 4, 2))]
#> [1]  1 24
which(copies > 21, arr.ind = TRUE)
#>   shelf slot room
#> A     1    4    2
#> B     2    4    2
#> C 3 4 2-
copies[, , 1]is a 3 x 4 matrix, the slice for the main room;copies["A", , ]is a 4 x 2 matrix with the slots as rows and the rooms as columns;copies[, "s2", "annex"]is a vector of length three. The manual’s example isa[2, , ], which gives a 4 x 2 array. -
drop = FALSEkeeps the extents of length one:dim(copies[, , 1, drop = FALSE])is3 4 1,dim(copies[1, 1, , drop = FALSE])is1 1 2. -
A wrong number of indices is an error (
copies[1, 2]for three dimensions givesincorrect number of dimensions), but a single index ignores the dimensions and uses the data vector:copies[10]is 10 andcopies[c(TRUE, FALSE, FALSE, FALSE)]selects every fourth value. -
slice.index(x, margin)gives, for each element, its index along dimensionmargin, socopies[slice.index(copies, 3) == 2]selects the second room, the same ascopies[, , 2]but as a vector and for any dimension. -
An index matrix has one column per dimension:
copies[rbind(c(1, 1, 1), c(3, 4, 2))]selects the first and the last copy, andwhich(copies > 21, arr.ind = TRUE)lists the three positions with the largest numbers, with the dimension names as column names.
Matrices and higher-dimensional arrays are covered in Matrices and Arrays; one thing from the R 4.6.0 NEWS belongs here: subassignment to a one-dimensional array with a name as the index (x["a"] <- v) no longer drops the array to a plain vector (R NEWS: Changes in R 4.6.0).
Lists
A list is a vector whose elements can be anything, so subsetting it raises the question that atomic vectors do not: do you want a list back or the thing inside? The manual puts the rule in one sentence: for lists one generally uses [[ to select any single element, whereas [ returns a list of the selected elements (The R Language Definition: Indexing; An Introduction to R: Lists). The script below uses a list of three book objects of the scenario, which is a list of lists, so every kind of nesting shows up.
source("scenario.R")

msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))

# A reading list: a list of three book objects
reading_list <- list(
  dispossessed = book("The Dispossessed", "Ursula K. Le Guin", year = 1974),
  pride = book("Pride and Prejudice", "Jane Austen", year = 1813),
  roofs = book("Loud Roofs", "Mara Quill", year = 2021)
)
length(reading_list)
#> [1] 3
names(reading_list)
#> [1] "dispossessed" "pride"        "roofs"

# [ returns a list, [[ returns the element itself
class(reading_list[1])
#> [1] "list"
class(reading_list[[1]])
#> [1] "book"
reading_list[["pride"]]$title
#> [1] "Pride and Prejudice"
reading_list$pride$year
#> [1] 1813
reading_list[c("pride", "roofs")]
#> $pride
#> <book> Pride and Prejudice (Jane Austen, 1813)
#>
#> $roofs
#> <book> Loud Roofs (Mara Quill, 2021)
#>

# A vector index in [[ walks down the nested structure, one level per element
reading_list[["pride"]][["year"]]
#> [1] 1813
reading_list[[c("pride", "year")]]
#> [1] 1813
reading_list[[c(2, 4)]]
#> [1] 1813
msg(reading_list[[c("pride", "isbn", "x")]])
#> [1] "subscript out of bounds"

# Negative and logical subscripts select lists the same way as vectors
names(reading_list[-1])
#> [1] "pride" "roofs"
years <- vapply(reading_list, \(b) b$year, numeric(1))
years
#> dispossessed        pride        roofs
#>         1974         1813         2021
names(reading_list[years > 1900])
#> [1] "dispossessed" "roofs"

# Out of bounds on a list
reading_list[4]
#> $<NA>
#> NULL
#>
msg(reading_list[[4]])
#> [1] "subscript out of bounds"
reading_list[["missing"]]
#> NULL
reading_list$missing
#> NULL
reading_list[["pr"]]
#> NULL
reading_list$pr$title
#> [1] "Pride and Prejudice"

# [ keeps only names, dim and dimnames; other attributes are dropped
attr(reading_list, "owner") <- "reading room"
attributes(reading_list[1:2])
#> $names
#> [1] "dispossessed" "pride"
#>
attributes(reading_list)$owner
#> [1] "reading room"-
reading_list[1]is a list of length one (class()is"list"),reading_list[[1]]is the book (class()is"book"). Because[returns a list, the printing ofreading_list[c("pride", "roofs")]goes through theprint.bookmethod once per element, with the names as$prideand$roofs. -
A chain
reading_list[["pride"]][["year"]]orreading_list$pride$yeargoes down one level at a time. A vector index in[[does the same:reading_list[[c("pride", "year")]]isreading_list[["pride"]][["year"]], andreading_list[[c(2, 4)]]is the fourth field of the second book, its year. The help page says thatalist[[i]]with a vectoriof lengthpis equivalent toalist[[i1]]...[[ip]], provided that all but the last indexing give a list. A wrong step is an error:reading_list[[c("pride", "isbn", "x")]]tries to use[["x"]]on a character string and givessubscript out of bounds. -
Negative and logical indexes select lists exactly as they select vectors, because a list is a vector.
reading_list[years > 1900], with the logical vector made byvapply(), keeps two books. -
Out of bounds.
reading_list[4]is a list with oneNULLelement with the name<NA>,reading_list[[4]]is an error, andreading_list[["missing"]]andreading_list$missingareNULL.NULLis a valid value for an element of a list, so aNULLresult does not tell you whether the element is missing or holdsNULL; use"missing" %in% names(reading_list)oris.null()on[[for that. The partial matching rules are those of the previous section:reading_list$pr$titleworks through$,reading_list[["pr"]]isNULL. -
[keepsnamesand drops every other attribute: afterattr(reading_list, "owner") <- "reading room",attributes(reading_list[1:2])has only thenames.
A list that has a class, like each book, can have [ and [[ methods of its own. The book class of the scenario does not define any, so the default methods run and book[1] is a plain list without the class. Defining [.book is the way to make a subset keep the class, and NextMethod() is the tool for it; see S3 Classes and Generics.
Data frames
A data frame is a list of equal-length columns with a class and row names, and [.data.frame is the method that gives it two modes of indexing. The help page of [.data.frame describes both. With a single index (x[i] or x[[i]]) it is indexed as a list of columns; with two indexes (x[i, j]) it is indexed like a matrix. The method is documented on R documentation: Extract.data.frame, and the language definition describes it in a paragraph as well (The R Language Definition: Indexing other structures).
source("scenario.R")

msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))
wmsg <- \(expr) tryCatch(expr, warning = \(w) conditionMessage(w))

# Dimensions and names of the books data frame
dim(books)
#> [1] 16  6
names(books)
#> [1] "title"  "author" "isbn"   "year"   "genre"  "pages"

# df[i, j]: rows and columns like a matrix
books[2, 4]
#> [1] 1813
books[1:3, c("title", "year")]
#>                  title year
#> 1     The Dispossessed 1974
#> 2  Pride and Prejudice 1813
#> 3   the quiet streets  2019
books[books$year > 2020, c("title", "year")]
#>             title year
#> 4      Loud Roofs 2021
#> NA           <NA>   NA
#> 10 THE LONG TABLE 2023
#> 15    Ten Winters 2022

# df[j] and df[[j]] and df$col treat the data frame as a list of columns
class(books["year"])
#> [1] "data.frame"
class(books[["year"]])
#> [1] "integer"
class(books$year)
#> [1] "integer"
books[c("title", "year")][1:2, ]
#>                 title year
#> 1    The Dispossessed 1974
#> 2 Pride and Prejudice 1813

# One column with a comma drops to a vector; one row stays a data frame
class(books[, "year"])
#> [1] "integer"
class(books[3, ])
#> [1] "data.frame"
head(books[, "year", drop = FALSE], 3)
#>   year
#> 1 1974
#> 2 1813
#> 3 2019
class(books[3, , drop = TRUE])
#> [1] "list"

# The one-subscript form ignores drop, with a warning
wmsg(books["year", drop = TRUE])
#> [1] "'drop' argument will be ignored"

# Rows by negative position and by sort order
head(books[-(1:13), "title"])
#> [1] "The Slow Comet"  "Ten Winters"     "Salt and Static"
books[order(books$year, decreasing = TRUE)[1:3], c("title", "year")]
#>             title year
#> 10 THE LONG TABLE 2023
#> 15    Ten Winters 2022
#> 4      Loud Roofs 2021

# Unknown columns
msg(books[, "publisher"])
#> [1] "undefined columns selected"
msg(books["publisher"])
#> [1] "undefined columns selected"
books[["publisher"]]
#> NULL
books$publisher
#> NULL
msg(books[["publisher", exact = TRUE]])
#> NULL

# Column partial matching: $ does it, [[ and [ do not
books$yea
#>  [1] 1974 1813 2019 2021 2016 2008   NA 1999 2012 2023 2005 2017 2020 2014 2022
#> [16] 2018
books[["yea"]]
#> NULL
wmsg(books[["yea", exact = NA]])
#> [1] "partial match of 'yea' to 'year'"The results of the script, form by form:
| Form | Result | Note |
|---|---|---|
|
a single value |
row 2, column 4: the year of "Pride and Prejudice" |
|
a data frame |
rows and columns like a matrix; the row names ( |
|
a data frame |
the list form: columns only, never drops |
|
a vector |
one column as a vector |
|
a vector |
a single column with a comma drops to a vector |
|
a data frame with one row |
a single row is not dropped by default |
|
a data frame |
keeps the data frame |
|
a list |
dropping a row has to be requested explicitly |
-
drop. The default of the data frame method is to drop to a vector when only one column is left, but not to drop when only one row is left. The warning section of the help page says that the default behaviour when only one row is left is equivalent to
drop = FALSE, and that dropping from a data frame to a list needsdrop = TRUEto be explicit. This is the same defensive argument as for matrices (R FAQ 7.5) and with the same reason:df[, cols]returns a data frame whencolshas two names and a vector when it has one, so any helper that takes the columns as an argument should usedf[, cols, drop = FALSE]or the list formdf[cols]. -
The one-index form ignores
drop, with a warning, because the list form never drops:books["year", drop = TRUE]gives'drop' argument will be ignored. The language definition says the same. -
Unknown columns.
books[, "publisher"]andbooks["publisher"]are errors with the textundefined columns selected;books[["publisher"]]andbooks$publisherareNULL. This is a difference that makes a typo indf$namesilent and a typo indf[, "name"]loud. -
Partial matching. There is no
$method for data frames, sobooks$yeauses the default method for lists and matches the columnyear(and returns it, silently unlesswarnPartialMatchDollarisTRUE).[[and[do not match column names partially, with the sameexactargument as for lists (theexact = NAcall shows the warningpartial match of 'yea' to 'year'). Row names are different: both[and[[extraction methods match row names partially, as the next script shows. -
A selection of rows or columns that keeps a data frame gives the result unique row names and column names, by
make.unique(), sobooks[c(1, 1, 2), ]has row names1,1.1and2.
source("scenario.R")

# Five books with row names that are short keys
five <- books[1:5, c("title", "year", "pages")]
rownames(five) <- c("dispossessed", "pride", "quiet", "loud", "ledger")
five["pride", ]
#>                     title year pages
#> pride Pride and Prejudice 1813   432

# Rows of a data frame are matched by name, and a prefix is accepted when it
# is unique (the help page of [.data.frame says so); columns are not
five["lo", "title"]
#> [1] "Loud Roofs"
five[c("lo", "l"), "title"]
#> [1] "Loud Roofs" NA

# For exact matching on row names use match()
five[match("lo", rownames(five)), "title"]
#> [1] NA
five["lo", ]
#>           title year pages
#> loud Loud Roofs 2021   198

# Selecting a row twice gives unique row names
five[c(1, 1, 2), c("title", "year")]
#>                              title year
#> dispossessed      The Dispossessed 1974
#> dispossessed.1    The Dispossessed 1974
#> pride          Pride and Prejudice 1813
five[c("pride", "pride"), "year"]
#> [1] 1813 1813

# Row names after filtering keep the original numbers
books[books$year > 2020 & !is.na(books$year), c("title", "year")]
#>             title year
#> 4      Loud Roofs 2021
#> 10 THE LONG TABLE 2023
#> 15    Ten Winters 2022
rownames(books[books$year > 2020 & !is.na(books$year), ])
#> [1] "4"  "10" "15"

# Renumber them with rownames<- NULL
filtered <- books[which(books$year > 2020), c("title", "year")]
rownames(filtered) <- NULL
filtered
#>            title year
#> 1     Loud Roofs 2021
#> 2 THE LONG TABLE 2023
#> 3 Ten Winters 2022five["lo", "title"] is "Loud Roofs" because "lo" is a unique prefix of the row name loud, and five[c("lo", "l"), "title"] has an NA for "l", which is a prefix of both loud and ledger. The help page recommends match() when exact matching of row names is wanted: five[match("lo", rownames(five)), "title"] is NA because no row has exactly that name. Rows keep their original row names after a filter (the row named 15 stays 15), and rownames(df) <- NULL renumbers them.
Rows by condition and the NA-row trap
The most common way of using [ on a data frame is a logical vector for the rows: df[df$year > 2000, ]. It has one trap that follows from the rule for NA in an index. When the condition is NA for a row, the row is selected as a row of NA values, and its row name is NA. No error and no warning says so. In the scenario, books$year has one missing value, the year of "Garden of Small Fires", so books$year > 2020 has one NA and the filtered result has four rows where three books were published after 2020. The same happens in the loans: a loan with no return date has no number of days.
source("scenario.R")

msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))

# books$year has one NA, so the comparison has one NA
books$year > 2020
#>  [1] FALSE FALSE FALSE  TRUE FALSE FALSE    NA FALSE FALSE  TRUE FALSE FALSE
#> [13] FALSE FALSE  TRUE FALSE
sum(is.na(books$year))
#> [1] 1

# The NA row trap: the NA in the logical index selects a row of NAs
recent <- books[books$year > 2020, c("title", "year")]
recent
#>             title year
#> 4      Loud Roofs 2021
#> NA           <NA>   NA
#> 10 THE LONG TABLE 2023
#> 15    Ten Winters 2022
nrow(recent)
#> [1] 4

# Three ways to keep only the rows that are TRUE
books[which(books$year > 2020), c("title", "year")]
#>             title year
#> 4      Loud Roofs 2021
#> 10 THE LONG TABLE 2023
#> 15    Ten Winters 2022
books[!is.na(books$year) & books$year > 2020, c("title", "year")]
#>             title year
#> 4      Loud Roofs 2021
#> 10 THE LONG TABLE 2023
#> 15    Ten Winters 2022
subset(books, year > 2020, select = c(title, year))
#>             title year
#> 4      Loud Roofs 2021
#> 10 THE LONG TABLE 2023
#> 15    Ten Winters 2022

# Overdue loans. A returned loan is overdue when it was out for more than
# loan_days days; an unreturned loan when it has been out that long at
# shelf_today. Both rules have NAs because some dates are missing.
returned_days <- loans$return_date - loans$loan_date
class(returned_days)
#> [1] "difftime"
overdue_returned <- !is.na(returned_days) & returned_days > loan_days
open_days <- shelf_today - loans$loan_date
overdue_open <- is.na(loans$return_date) & !is.na(open_days) &
  open_days > loan_days
c(returned = sum(overdue_returned), still_out = sum(overdue_open))
#>  returned still_out
#>        25         7

overdue <- loans[overdue_returned | overdue_open, ]
nrow(overdue)
#> [1] 32
head(overdue[, c("loan_id", "member", "loan_date", "return_date")], 4)
#>   loan_id        member  loan_date return_date
#> 4    L004 Eva Lindqvist 2025-01-26  2025-02-21
#> 5    L005    Ben Okafor 2025-02-19  2025-03-17
#> 7    L007     Grace Liu 2025-03-11  2025-04-04
#> 9    L009    Hugo Silva 2025-03-30  2025-04-30

# The naive filter returns a row of NAs for every NA in the comparison: the
# unreturned loans and the loan with the impossible date
naive <- loans[returned_days > loan_days, ]
nrow(naive)
#> [1] 33
sum(is.na(naive$loan_id))
#> [1] 8
head(rownames(naive[is.na(naive$loan_id), ]), 3)
#> [1] "NA"   "NA.1" "NA.2"

# Dropping rows with -which() is a trap: when nothing matches, -integer(0)
# selects nothing at all
too_long <- which(returned_days > 1000)
too_long
#> integer(0)
nrow(loans[-too_long, ])
#> [1] 0-
recenthas a row namedNAwithNAin every column. Three fixes select only the rows that areTRUE:which()(which dropsNAas notTRUE), an explicit test!is.na(books$year) & books$year > 2020, andsubset(), which the help page documents as treating missing values in the condition as false. -
Overdue loans. A returned loan is overdue when it was out for more than
loan_daysdays; a loan that has not been returned is overdue when it has been out that long atshelf_today.returned_daysis adifftime, andreturned_days > loan_dayscompares days with the number 21. The two rules each have missing values: an unreturned loan has no return date and one loan has the impossible date2025-02-30, which was read asNA. The script therefore protects each rule with!is.na(), and counts 25 overdue returned loans and 7 overdue unreturned ones, 32 in total. The naive filterloans[returned_days > loan_days, ]has 33 rows, 25 real ones and 8 rows ofNA(the 7 unreturned loans and the loan with the impossible date), with row namesNA,NA.1,NA.2and so on, because row names have to be unique. -
The
-which()trap. Dropping the rows that match a condition asloans[-which(cond), ]fails when no row matches:which()returnsinteger(0),-integer(0)isinteger(0), and an empty positive index selects nothing, so the result has no rows at all instead of all of them. Write the negation in the condition (loans[!cond, ], with theNAhandled) instead of in the index.
The rule is general: every comparison that has an NA in its data has an NA in its result, and [ turns an NA in a logical index into an NA element or row. Missing values are covered in Missing and Special Values.
Finding positions: which(), head(), tail(), match() and %in%
Indexing with a logical vector selects values. Getting positions instead of values is the job of which() and of the functions around it, and positions are what [ needs when the condition has NA.
source("scenario.R")

msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))

days <- as.integer(loans$return_date - loans$loan_date)
names(days) <- loans$loan_id
first_ten <- days[1:10]
first_ten
#> L001 L002 L003 L004 L005 L006 L007 L008 L009 L010
#>   21   10    1   26   26   17   24   10   31   21

# which() turns a logical vector into positions; NA counts as not TRUE
which(first_ten > loan_days)
#> L004 L005 L007 L009
#>    4    5    7    9
which(is.na(first_ten))
#> named integer(0)
which(c(a = TRUE, b = NA, c = TRUE))
#> a c
#> 1 3
which(first_ten > 1000)
#> named integer(0)
msg(which(c(1, 0, 1)))
#> [1] "argument to 'which' is not logical"

# which.max() and which.min() return the first extreme, with its name
which.max(first_ten)
#> L009
#>    9
which.min(first_ten)
#> L003
#>    3
which.max(c(NA, 3, 3))
#> [1] 2
which.max(c(NA_integer_, NA_integer_))
#> integer(0)
first_ten[which.max(first_ten)]
#> L009
#>   31
which(first_ten == max(first_ten))
#> L009
#>    9

# arr.ind = TRUE for matrices and arrays; the other way round is arrayInd()
grid <- matrix(first_ten, nrow = 2, byrow = TRUE)
which(grid > loan_days)
#> [1] 4 7 8 9
which(grid > loan_days, arr.ind = TRUE)
#>      row col
#> [1,]   2   2
#> [2,]   1   4
#> [3,]   2   4
#> [4,]   1   5
arrayInd(c(4, 5), dim(grid))
#>      [,1] [,2]
#> [1,]    2    2
#> [2,]    1    3

# head() and tail(): first and last n, and negative n counts from the other end
head(first_ten, 3)
#> L001 L002 L003
#>   21   10    1
tail(first_ten, 3)
#> L008 L009 L010
#>   10   31   21
head(first_ten, -7)
#> L001 L002 L003
#>   21   10    1
tail(first_ten, -7)
#> L008 L009 L010
#>   10   31   21
head(first_ten, 0)
#> named integer(0)
head(first_ten, 100)
#> L001 L002 L003 L004 L005 L006 L007 L008 L009 L010
#>   21   10    1   26   26   17   24   10   31   21

# head() and tail() on a data frame take rows; keepnums labels tail rows
head(books[, c("title", "year")], 3)
#>                  title year
#> 1     The Dispossessed 1974
#> 2  Pride and Prejudice 1813
#> 3   the quiet streets  2019
tail(books[, c("title", "year")], 2)
#>              title year
#> 15     Ten Winters 2022
#> 16 Salt and Static 2018
tail(grid, 1)
#>      [,1] [,2] [,3] [,4] [,5]
#> [2,]   17   24   10   31   21
tail(grid, 1, keepnums = FALSE)
#>      [,1] [,2] [,3] [,4] [,5]
#> [1,]   17   24   10   31   21

# match() and %in%: positions and membership
ids <- c("L003", "L999", "L001")
match(ids, names(first_ten))
#> [1]  3 NA  1
ids %in% names(first_ten)
#> [1]  TRUE FALSE  TRUE
first_ten[match(ids, names(first_ten))]
#> L003 <NA> L001
#>    1   NA   21
first_ten[ids[ids %in% names(first_ten)]]
#> L003 L001
#>    1   21

# match() returns the first position for duplicates, and can map between
# tables, which is how a lookup join is done in base R
match(c("978-0-14-143951-8", "nope"), c("x", "978-0-14-143951-8"))
#> [1]  2 NA
isbn <- normalise_isbn(books$isbn)
head(books$title[match(loans$isbn, isbn)], 4)
#> [1] "Pride and Prejudice"   "The Dispossessed"      "Loud Roofs"
#> [4] "Garden of Small Fires"
sum(is.na(match(loans$isbn, isbn)))
#> [1] 1
nomatch <- match(loans$isbn, isbn, nomatch = 0L)
sum(nomatch == 0L)
#> [1] 1
Source: R documentation: which
-
which(x)returns the positions of theTRUEvalues of a logical vector, with the names ofx;NAis treated asFALSE. The help page says thatwhich(x)isseq_along(x)[!is.na(x) & x]. It only accepts a logical argument:which(c(1, 0, 1))givesargument to 'which' is not logical. When nothing isTRUEthe result is an integer vector of length zero, with the names attribute (named integer(0)) whenxhas names. -
which.max(x)andwhich.min(x)return the position of the first maximum or minimum, with its name, and ignoreNA.which.max(c(NA, 3, 3))is 2, the first of two ties, and an all-NAargument givesinteger(0). Usewhich(x == max(x))for all of the ties (R documentation: which.min). -
which(x, arr.ind = TRUE)on an array returns the matrix of indices, andarrayInd(ind, .dim)converts positions for a given shape.arr.indmust be a singleTRUE; R 4.1.3 madewhich()check this instead of coercing the argument to logical and taking its first element (R NEWS: Changes in R 4.1.3). For a matrix withoutdimnamesthe columns of the result are calledrowandcol. -
head(x, n)andtail(x, n)return the first or lastnelements, or rows of a data frame or matrix. A negativenmeans all but the lastabs(n)elements forhead()and all but the firstabs(n)elements fortail():head(first_ten, -7)is the first three andtail(first_ten, -7)is the last three. A value ofnlarger than the length returns everything and0returns an empty object of the same type. For matrices and data framestail()labels the rows with their original numbers (keepnums = TRUE), for vectors it does not;keepnums = FALSEremoves the labels. The arguments are documented on R documentation: head; R 4.0.0 extendedhead()andtail()to arrays with a vectorn, which replaced the argumentaddrownumswithkeepnums(the old argument is deprecated), and R 4.3.0 made them signal an error ifnis not numeric (R NEWS: Changes in R 4.0.0 and 4.3.0). -
match(x, table)returns for each element ofxthe position of its first match intable, orNA.x %in% tableis the logical version,match(x, table, nomatch = 0) > 0, and it never returnsNA.first_ten[match(ids, names(first_ten))]selects by a vector of ids, with anNAfor the id that is not there, which is the lookup of a join in base R:books$title[match(loans$isbn, isbn)]gives the title of every loan, andnomatch = 0Lturns the one unmatched ISBN (the loan with the 12-digit ISBN) into a zero that can be tested. For one search value, the help page saysmatch(a, x)ismin(which(x == a))but much more efficient (R documentation: match).
The advice is to use which() when the result will be an index, in a loop that needs the positions, or when NA must be excluded, and to use the logical vector itself when a filter feeds sum() or mean() of the TRUE values or when the NA values are meant to be carried.
Sub-assignment
An index on the left of an assignment changes part of an object. The help page names it subassignment: the part of x that is indexed is set to the value of the right-hand side, no partial matching of character indexes is done, and the left-hand side is coerced as needed to accept the values. The form is x[i] <- value, x[i, j] <- value, x[[i]] <- value and x$name <- value (R documentation: Extract; The R Language Definition: Subset assignment). The result is a new value that is bound to the name: R evaluates a call to the replacement function and rebinds the variable, and it avoids the copy when no other name refers to the vector, a mechanism described in Assignment, Names and Values.
Vectors
The next script applies the rules to the loan lengths of the first scripts: replacement by position, by name and by condition, recycling, extension of the vector, a change of type, NA in the index and the empty index.
source("scenario.R")

msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))

# warns() lets expr finish and returns the text of the warnings it gave
warns <- function(expr) {
  seen <- character()
  withCallingHandlers(
    expr,
    warning = \(w) {
      seen <<- c(seen, conditionMessage(w)) # nolint: assignment_linter.
      invokeRestart("muffleWarning")
    }
  )
  seen
}

days <- as.integer(loans$return_date - loans$loan_date)
names(days) <- loans$loan_id
x <- days[1:6]
x
#> L001 L002 L003 L004 L005 L006
#>   21   10    1   26   26   17

# Replace by position, by name, by condition
x[1] <- 20L
x["L002"] <- 11L
x[x > loan_days] <- loan_days
x
#> L001 L002 L003 L004 L005 L006
#>   20   11    1   21   21   17

# Recycling of the value
x[1:4] <- 0L
x
#> L001 L002 L003 L004 L005 L006
#>    0    0    0    0   21   17
x[c(TRUE, FALSE)] <- c(7L, 8L, 9L)
x
#> L001 L002 L003 L004 L005 L006
#>    7    0    8    0    9   17

# The value is recycled, and a warning says so when its length does not
# divide the number of replaced items; the assignment is still done
y <- x
warns(y[1:4] <- 1:2)
#> character(0)
y
#> L001 L002 L003 L004 L005 L006
#>    1    2    1    2    9   17
warns(y[1:4] <- 1:3)
#> [1] "number of items to replace is not a multiple of replacement length"
y
#> L001 L002 L003 L004 L005 L006
#>    1    2    3    1    9   17

# Assigning beyond the end extends the vector and pads with NA
z <- x[1:3]
z[6] <- 99L
z
#> L001 L002 L003
#>    7    0    8   NA   NA   99
z["new"] <- 5L
z
#> L001 L002 L003                 new
#>    7    0    8   NA   NA   99    5
length(z)
#> [1] 7

# A zero-length value is an error, unless the index also selects nothing
msg(z[1:2] <- integer(0))
#> [1] "replacement has length zero"
z[integer(0)] <- integer(0)
z[0] <- 1L
z
#> L001 L002 L003                 new
#>    7    0    8   NA   NA   99    5

# The type of the vector changes to fit the value
typeof(z)
#> [1] "integer"
z[2] <- 2.5
typeof(z)
#> [1] "double"
z[3] <- "late"
typeof(z)
#> [1] "character"
z
#>   L001   L002   L003                         new
#>    "7"  "2.5" "late"     NA     NA   "99"    "5"

# NA in the index of an assignment
w <- c(a = 1, b = 2, c = 3)
w[NA] <- 0
w
#> a b c
#> 1 2 3
w[c(1, NA)] <- 10
w
#>  a  b  c
#> 10  2  3
msg(w[c(1, NA)] <- c(8, 9))
#> [1] "NAs are not allowed in subscripted assignments"
w[c(TRUE, NA, FALSE)] <- 5
w
#> a b c
#> 5 2 3

# Negative and zero indices in an assignment
w[-1] <- 0
w
#> a b c
#> 5 0 0
w[c(-1, 0)] <- 7
w
#> a b c
#> 5 7 7

# x[] <- keeps the shape and attributes; x <- replaces the object
v <- c(a = 1, b = 2, c = 3)
v[] <- 0
v
#> a b c
#> 0 0 0
v <- 0
v
#> [1] 0

# Sequential assignment: the last value wins for a repeated index
u <- numeric(3)
u[c(1, 1, 2)] <- c(10, 20, 30)
u
#> [1] 20 30  0
Source: R documentation: Extract
-
Recycling. The value is recycled to the length of the selection:
x[1:4] <- 0Lassigns four zeros. When its length does not divide the number of replaced items, the assignment is still done and R warns withnumber of items to replace is not a multiple of replacement length:y[1:4] <- 1:3gives 1, 2, 3, 1. Thewarns()helper shows the warning and lets the assignment run, which a plaintryCatch(warning = ...)would not do, because the handler leaves the expression before the assignment completes. -
Extension. An index beyond the end extends the vector and pads the gap with
NA:z[6] <- 99Lon a vector of length three gives six elements, and a new name extends it too (z["new"] <- 5L). The padded elements have the empty name"". -
A value of length zero.
z[1:2] <- integer(0)is the errorreplacement has length zero. If the index also selects nothing (z[integer(0)] <- integer(0),z[0] <- 1L), nothing happens and there is no error. -
Type change. The vector takes the higher of the types of
xandvaluein the hierarchy raw, logical, integer, double, complex, character, list, expression. Assigning2.5to an integer vector makes it double, and assigning a string turns everything into character ("7","2.5","late"), withNAstayingNA. Attributes are kept, andnames,dimanddimnamesare adjusted. -
NA in the index. When replacing, an
NAindex selects nothing. As there is ambiguity about whether the corresponding element of the value should be used, anNAin the index is only allowed if the value has length one:w[c(1, NA)] <- 10changes the first element, andw[c(1, NA)] <- c(8, 9)is the errorNAs are not allowed in subscripted assignments. A logicalNAindex (w[NA] <- 0) changes nothing. The help page records the history: S documented that anNAindex selects nowhere but still uses up an element of the value, and R has not done that. -
Negative and zero indexes work as for extraction (
w[-1] <- 0assigns to all but the first). -
Order. Subassignment is done sequentially, so if an index is repeated the last value wins:
u[c(1, 1, 2)] <- c(10, 20, 30)leaves20and30. -
The empty index.
v[] <- 0replaces every value and keeps all attributes, whilev <- 0replaces the object, which now has no names. The empty index is what to use to reset the values of an object while preserving its shape. -
In a function, a replacement such as
names(x)[2] <- "b"orx[i] <- vis applied to a local copy, unless the function uses<<-(see Functions).
Lists: NULL deletes, list(NULL) stores
For lists the replacement has one rule with a very common consequence: a value of NULL deletes the corresponding element. The help page says that this is so in all three kinds of replacement ([<-, [[<- and $<-), and that to set entries to NULL you need x[i] <- list(NULL). The R FAQ has it as entry 7.1: use x[i] <- list(NULL) to set component i of the list x to NULL, and do not set x[i] or x[[i]] to NULL, because this removes the component (R FAQ 7.1: How can I set components of a list to NULL?).
source("scenario.R")

msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))

entry <- list(title = "Dune", pages = 412L, genre = "Science fiction")
str(entry)
#> List of 3
#>  $ title: chr "Dune"
#>  $ pages: int 412
#>  $ genre: chr "Science fiction"

# Assign with [[ and $: add, replace
entry[["year"]] <- 1965L
entry$publisher <- "Chilton"
names(entry)
#> [1] "title"     "pages"     "genre"     "year"      "publisher"
entry$pages <- 400L
entry$pages
#> [1] 400

# Replacement never matches a name partially: $<- with a prefix adds a new
# element instead of changing pages
entry$pag <- 1L
names(entry)
#> [1] "title"     "pages"     "genre"     "year"      "publisher" "pag"
entry$pag <- NULL

# Assigning NULL with [[ or $ removes the element
entry[["publisher"]] <- NULL
names(entry)
#> [1] "title" "pages" "genre" "year"
entry$year <- NULL
names(entry)
#> [1] "title" "pages" "genre"

# FAQ 7.1: to store NULL, assign a list holding NULL with [
entry["genre"] <- list(NULL)
str(entry)
#> List of 3
#>  $ title: chr "Dune"
#>  $ pages: int 400
#>  $ genre: NULL
length(entry)
#> [1] 3
entry["pages"] <- NULL
names(entry)
#> [1] "title" "genre"

# Removing several at once, and removing a name that is not there
entry[c("title", "genre")] <- NULL
length(entry)
#> [1] 0
entry$missing <- NULL
length(entry)
#> [1] 0

# [<- with a list value replaces several elements; the value is recycled
point <- list(a = 1, b = 2, c = 3)
point[c("a", "b")] <- list(10, 20)
unlist(point)
#>  a  b  c
#> 10 20  3
point[c("a", "b", "c")] <- list(0)
unlist(point)
#> a b c
#> 0 0 0
msg(point[c("a", "b")] <- list())
#> [1] "replacement has length zero"

# Recursive assignment with a vector index
nested <- list(a = list(b = 9, c = "hello"), d = 1:5)
nested[[c("a", "b")]] <- "new"
nested$a$b
#> [1] "new"
nested[["a"]][["c"]] <- NULL
str(nested)
#> List of 2
#>  $ a:List of 1
#>   ..$ b: chr "new"
#>  $ d: int [1:5] 1 2 3 4 5

# A NULL list becomes a list on [[<- (R 4.0.0 and later), even for length one
out <- NULL
out[["first"]] <- 1
class(out)
#> [1] "list"
out$second <- "two"
str(out)
#> List of 2
#>  $ first : num 1
#>  $ second: chr "two"

# An atomic vector cannot hold NULL or more than one value in a [[ slot
v <- c(a = 1, b = 2)
msg(v[["a"]] <- NULL)
#> [1] "replacement has length zero"
msg(v[["c"]] <- 1:2)
#> [1] "more elements supplied than there are to replace"

# Lists of books: replace one book, remove another
reading_list <- list(
  dispossessed = book("The Dispossessed", "Ursula K. Le Guin", year = 1974),
  pride = book("Pride and Prejudice", "Jane Austen", year = 1813)
)
reading_list[["pride"]]$pages <- 432L
reading_list[["pride"]]$pages
#> [1] 432
reading_list$dispossessed <- NULL
names(reading_list)
#> [1] "pride"-
entry[["publisher"]] <- NULLandentry$year <- NULLremove elements;entry["genre"] <- list(NULL)keeps agenreelement whose value isNULL(str()shows$ genre: NULL, andlength(entry)is still three);entry["pages"] <- NULLremovespages. -
Assigning
NULLto a name that does not exist is not an error (entry$missing <- NULL), andentry[c("title", "genre")] <- NULLremoves several elements in one step. -
[<-with a list value replaces several elements and recycles the list (point[c("a", "b", "c")] <- list(0)sets three elements to 0). An empty list value is the errorreplacement has length zero. -
Replacement does not match partially.
entry$pag <- 1Ladds a new element calledpagrather than changingpages; extraction with$would have matched. The help page says that no partial matching is done in subassignment. -
A vector index in
[[<-replaces a nested element (nested[[c("a", "b")]] <- "new"), andnested[["a"]][["c"]] <- NULLremoves a nested one. -
$<-onNULLfirst coerces it tolist(), and so does[[<-; in R versions before 4.0.0 a length-one value assigned with[[<-toNULLgave an atomic vector, and since R 4.0.0 it gives a list (R NEWS: Changes in R 4.0.0).out <- NULL; out[["first"]] <- 1has class"list". -
An atomic vector cannot hold
NULLor a longer value in a single slot:v[["a"]] <- NULLisreplacement has length zeroandv[["c"]] <- 1:2ismore elements supplied than there are to replace. -
For the books,
reading_list[["pride"]]$pages <- 432Lchanges a field of a book inside a list, which is a nested replacement, explained in the section after the data frames;reading_list$dispossessed <- NULLremoves a book.
Data frames
A data frame is a list, so the list forms work, and the matrix forms follow the rules of [<-.data.frame. The replacement methods add whole columns by naming a column that does not exist; columns are added at the right-hand edge, rows can be added at any row after the last one and the columns are filled with missing values; and a NULL value deletes the column. Missing values in the indices are not allowed for replacement.
source("scenario.R")

msg <- \(expr) tryCatch(expr, error = \(e) conditionMessage(e))

# warns() lets expr finish and returns the text of the warnings it gave
warns <- function(expr) {
  seen <- character()
  withCallingHandlers(
    expr,
    warning = \(w) {
      seen <<- c(seen, conditionMessage(w)) # nolint: assignment_linter.
      invokeRestart("muffleWarning")
    }
  )
  seen
}

stock <- books[, c("title", "year", "pages")]
head(stock, 4)
#>                  title year pages
#> 1     The Dispossessed 1974   387
#> 2  Pride and Prejudice 1813   432
#> 3   the quiet streets  2019   214
#> 4           Loud Roofs 2021   198

# A new column: a single value is recycled to the number of rows
stock$on_loan <- FALSE
stock$age <- 2026L - stock$year
stock[["short"]] <- stock$pages < 200
head(stock, 3)
#>                  title year pages on_loan age short
#> 1     The Dispossessed 1974   387   FALSE  52 FALSE
#> 2  Pride and Prejudice 1813   432   FALSE 213 FALSE
#> 3   the quiet streets  2019   214   FALSE   7 FALSE

# A value of the wrong length is an error
msg(stock$bad <- 1:3)
#> [1] "replacement has 3 rows, data has 16"
msg(stock$bad <- 1:5)
#> [1] "replacement has 5 rows, data has 16"
stock$bad <- 1:4
ncol(stock)
#> [1] 7
stock$bad <- NULL

# Update cells by condition. pages has NAs, so the condition has NAs too
msg(stock[stock$pages < 100, "pages"] <- NA)
#> [1] "missing values are not allowed in subscripted assignments of data frames"
stock$pages[which(stock$pages < 100)] <- NA
stock$pages
#>  [1] 387 432 214 198 301  NA  NA 280 352 256  NA 410 175 322  NA 244

# Update with an explicit value; the condition handled with is.na()
stock[!is.na(stock$pages) & stock$pages > 400, "pages"] <- 400L
stock$pages
#>  [1] 387 400 214 198 301  NA  NA 280 352 256  NA 400 175 322  NA 244

# Rows: add, replace, remove
stock[nrow(stock) + 1L, ] <- list("New Book", 2026L, 100L, TRUE, 0L, TRUE)
tail(stock, 2)
#>              title year pages on_loan age short
#> 16 Salt and Static 2018   244   FALSE   8 FALSE
#> 17        New Book 2026   100    TRUE   0  TRUE
stock[stock$title == "New Book", "pages"] <- 120L
stock <- stock[stock$title != "New Book", ]
nrow(stock)
#> [1] 16

# Columns: remove with NULL or with negative subscripts
stock$short <- NULL
names(stock)
#> [1] "title"   "year"    "pages"   "on_loan" "age"
stock <- stock[, -2]
names(stock)
#> [1] "title"   "pages"   "on_loan" "age"

# Replace a whole column through the list interface
books_copy <- books
books_copy["title"] <- list(trimws(books$title))
books_copy[["genre"]] <- tolower(trimws(books$genre))
books_copy$author <- NULL
head(books_copy, 3)
#>                 title              isbn year           genre pages
#> 1    The Dispossessed 978-0-306-40615-7 1974 science fiction   387
#> 2 Pride and Prejudice 978-0-14-143951-8 1813         classic   432
#> 3   the quiet streets     9780001000100 2019         fiction   214

# A logical matrix selects cells of a data frame for replacement
nums <- books[, c("year", "pages")]
nums[is.na(nums)] <- 0L
colSums(nums == 0L)
#>  year pages
#> 1 2-
New columns.
stock$on_loan <- FALSErecycles the single value to the 16 rows.stock$bad <- 1:3is the errorreplacement has 3 rows, data has 16; a value is replicated only when an exact number of repeats fits, so1:4is accepted and repeated four times, and1:5is an error. A value of length one is the usual and safest case. -
Update by condition. The form
df[df$pages < 100, "pages"] <- NAis the one to be careful with when the condition can beNA: with anNAinstock$pagesit is the errormissing values are not allowed in subscripted assignments of data frames. The data frame form refuses anNAin the row index altogether, while the vector formx[cond] <- vaccepts it when the value has length one and then leaves the elements with anNAcondition unchanged. Either way, write the condition so that it has noNA: usewhich()(stock$pages[which(stock$pages < 100)] <- NA) or!is.na()in the condition. -
Rows.
stock[nrow(stock) + 1L, ] <- list(...)appends a row from a list with one element for each column, and a condition replaces cells in selected rows; a filter keeps rows (stock[stock$title != "New Book", ]). -
Columns.
stock$short <- NULLremoves a column, as doesstock[, -2](by position, in a copy), andstock["title"] <- list(...)replaces a whole column through the list interface, as do[[and$. For[, the replacement value can be a list: each element is used to replace (part of) one column, andNULLelements delete columns when the replacement does not select rows. -
Logical matrix.
nums[is.na(nums)] <- 0Lreplaces theNAcells of every column in one step: for replacement a logical matrix index must have the same dimension as the data frame, and the replacement is done one column at a time, each value coerced to the type of the column it goes to. This is the replacement form of the matrix index that the help page advises against for extraction.
How a replacement call is evaluated
x[i] <- v looks like an assignment to a part of x, but R evaluates it as a call to the replacement function named [<- and assigns the result to x. The language definition spells out the steps with a temporary variable that has the internal name *tmp*; the listing below is that conceptual expansion, a fragment and not a script to run. A function whose name is another name followed by <- works the same way, and its last argument must be called value. The second part of the listing is the nested case: names(x)[3] <- "Three" is two replacements, evaluated from the inside out, where the value of the inner [<- call becomes the value of the outer names<- call.
x[3:5] <- 13:15
# is evaluated as if it were
`*tmp*` <- x
x <- "[<-"(`*tmp*`, 3:5, value = 13:15)
rm(`*tmp*`)

names(x)[3] <- "Three"
# is evaluated as if it were
`*tmp*` <- x
x <- "names<-"(`*tmp*`, value = "[<-"(names(`*tmp*`), 3, value = "Three"))
rm(`*tmp*`)The index is converted to numbers first and the elements are replaced in order along them, as if by a for loop. The same mechanism works with <<-, where only the target variable is looked up in the enclosing environment and the other names of the expression are evaluated in the current one; the manual advises against a local variable with the same name as the target of a superassignment. The next script runs the equivalent steps by hand, defines a replacement function of its own and uses the ones that ship with R.
source("scenario.R")

# names(x)[2] <- "b" is a nested replacement: R evaluates it in steps
x <- c(a = 1, b = 2, c = 3)
names(x)[2] <- "beta"
x
#>    a beta    c
#>    1    2    3

# The call R makes, written out by hand (the *tmp* variable is internal)
y <- c(a = 1, b = 2, c = 3)
y <- `names<-`(y, value = `[<-`(names(y), 2, value = "beta"))
identical(x, y)
#> [1] TRUE

# The same steps, one at a time
nm <- names(y)
nm[2] <- "second"
names(y) <- nm
y
#>      a second      c
#>      1      2      3

# [<- is an ordinary function that returns the modified copy
z <- c(1, 2, 3)
`[<-`(z, 2, 99)
#> [1]  1 99  3
z
#> [1] 1 2 3

# A replacement function is a function whose name ends in <- and whose last
# argument is called value. This one sets the title of a book.
`title<-` <- function(x, value) {
  stopifnot(inherits(x, "book"))
  x$title <- value
  x
}
dune <- book("Dune", "Frank Herbert", year = 1965)
title(dune) <- "Dune Messiah"
dune$title
#> [1] "Dune Messiah"

# Used in a nested complex assignment, it composes with [[ and $
shelf_list <- list(first = dune)
title(shelf_list$first) <- "Children of Dune"
shelf_list$first$title
#> [1] "Children of Dune"
title(shelf_list[["first"]]) <- "God Emperor of Dune"
shelf_list[["first"]]$title
#> [1] "God Emperor of Dune"

# is.na<- sets elements to NA by position
loan_len <- c(L001 = 21L, L002 = 10L, L003 = 1L)
is.na(loan_len) <- 2
loan_len
#> L001 L002 L003
#>   21   NA    1
is.na(loan_len) <- "L003"
loan_len
#> L001 L002 L003
#>   21   NA   NA

# Other replacement functions that act like sub-assignment
m <- matrix(1:6, nrow = 2)
dim(m) <- c(3, 2)
m
#>      [,1] [,2]
#> [1,]    1    4
#> [2,]    2    5
#> [3,]    3    6
dimnames(m) <- list(c("a", "b", "c"), c("x", "y"))
m["b", "y"] <- 0L
m
#>   x y
#> a 1 4
#> b 2 0
#> c 3 6
f <- factor(c("a", "b", "a"))
levels(f)[2] <- "B"
f
#> [1] a B a
#> Levels: a B-
The first statement of the script,
names(x)[2] <- "beta", and the hand-written call in the second block give identical results (identical()isTRUE); the third block takes the same steps with an ordinary variable,nm. -
Calling
[<-directly prints the modified copy and leaveszunchanged: it is the assignment that rebinds the name. That is why a replacement function must return the whole modified object. -
A replacement function is any function called
name<-with a final argumentvalue. Thetitle<-in the script checks that its argument is abookand returns the changed copy, and thentitle(dune) <- "Dune Messiah"works at the top level,title(shelf_list$first) <- ...works on a list element andtitle(shelf_list[["first"]]) <- ...works with[[, because each step of a nested replacement calls the replacement function of the outer part with the result of the inner replacement. The functionsnames<-,dim<-,dimnames<-,levels<-andattr<-are all of this kind, as the last block shows. -
is.na(x) <- iis another replacement function: it sets the elements at position (or name)itoNA; the help page ofis.nadocuments it with the replacement form (R documentation: NA).
subset() versus [
subset() is a function that selects rows and columns with a condition written in terms of the columns. It is documented as a convenience function intended for use interactively, and it has a warning that it should not be used for programming (R documentation: subset). The condition year > 2020 is not evaluated in the calling environment: subset() evaluates it in the data frame, so the columns are variables. That is non-standard evaluation, and Evaluation and Non-Standard Evaluation explains the mechanism. The help page lists the differences from [:
-
for a vector,
subset(x, cond)isx[cond & !is.na(cond)]: missing values in the condition count asFALSE, so there is no NA-row trap; -
for a data frame, the argument
subsetworks on the rows and the argumentselecton the columns.selectis an expression in which the column names have been replaced by the column numbers, so ranges (title:year), negative selections (-c(isbn, genre)) andc()of names all work without quotes; -
the argument
dropis passed to[, but its default isFALSEfor data frames and matrices, which is different from the default of the indexing operator; -
factors are not cleaned: unused levels remain, and
droplevels()removes them (R documentation: droplevels); -
since R 4.3.0 the data frame method warns about extra arguments, which typically catches
=written where==was meant, as insubset(books, year = 2020)(R NEWS: Changes in R 4.3.0).
source("scenario.R")

# warns() lets expr finish and returns the text of the warnings it gave
warns <- function(expr) {
  seen <- character()
  withCallingHandlers(
    expr,
    warning = \(w) {
      seen <<- c(seen, conditionMessage(w)) # nolint: assignment_linter.
      invokeRestart("muffleWarning")
    }
  )
  seen
}

# subset() evaluates its condition inside the data frame, and drops NA rows
subset(books, year > 2020)[, c("title", "year")]
#>             title year
#> 4      Loud Roofs 2021
#> 10 THE LONG TABLE 2023
#> 15    Ten Winters 2022
books[books$year > 2020, c("title", "year")]
#>             title year
#> 4      Loud Roofs 2021
#> NA           <NA>   NA
#> 10 THE LONG TABLE 2023
#> 15    Ten Winters 2022

# select= takes unquoted names, ranges and negative selections
subset(books, pages > 400, select = c(title, pages))
#>                  title pages
#> 2  Pride and Prejudice   432
#> 12    Notes on Gravity   410
subset(books, pages > 400, select = title:year)
#>                  title       author              isbn year
#> 2  Pride and Prejudice  Jane Austen 978-0-14-143951-8 1813
#> 12    Notes on Gravity Elias Moreau 978-0-01-000104-4 2017
subset(books, pages > 400, select = -c(isbn, genre))
#>                  title       author year pages
#> 2  Pride and Prejudice  Jane Austen 1813   432
#> 12    Notes on Gravity Elias Moreau 2017   410
subset(books, genre == "Mystery", select = -c(isbn, genre, author))
#>              title year pages
#> 5  Midnight Ledger 2016   301
#> 16 Salt and Static 2018   244

# drop = FALSE by default, unlike [
class(subset(books, pages > 400, select = title))
#> [1] "data.frame"
class(books[books$pages > 400 & !is.na(books$pages), "title"])
#> [1] "character"
class(subset(books, pages > 400, select = title, drop = TRUE))
#> [1] "character"

# For a plain vector, subset() is x[subset & !is.na(subset)]
days <- as.integer(loans$return_date - loans$loan_date)
subset(days, days > loan_days)[1:5]
#> [1] 26 26 24 31 36

# The condition can use any column, and the data frame is searched first
cutoff <- 2015
subset(books, year > cutoff & pages < 250, select = c(title, year, pages))
#>                   title year pages
#> 3    the quiet streets  2019   214
#> 4            Loud Roofs 2021   198
#> 13        Orchard Logic 2020   175
#> 16      Salt and Static 2018   244

# The same with [ needs the name of the data frame each time
books[
  which(books$year > cutoff & books$pages < 250),
  c("title", "year", "pages")
]
#>                   title year pages
#> 3    the quiet streets  2019   214
#> 4            Loud Roofs 2021   198
#> 13        Orchard Logic 2020   175
#> 16      Salt and Static 2018   244

# subset() on a matrix needs a logical vector, and its drop default is FALSE
m <- matrix(1:6, nrow = 3, dimnames = list(NULL, c("p", "q")))
subset(m, m[, "p"] > 1)
#>      p q
#> [1,] 2 5
#> [2,] 3 6
subset(m, m[, "p"] > 1, select = q)
#>      q
#> [1,] 5
#> [2,] 6

# A single = where == was meant is caught since R 4.3.0: year = 2020 is not
# a condition, so it is reported and the whole data frame comes back
warns(nrow(subset(books, year = 2020)))
#> [1] "In subset.data.frame(books, year = 2020) :\n extra argument ‘year’ will be disregarded"
nrow(suppressWarnings(subset(books, year = 2020)))
#> [1] 16

# Factor levels are not dropped by subset() or by [, droplevels() does it
g <- factor(c("a", "b", "c"))
levels(subset(g, g != "c"))
#> [1] "a" "b" "c"
levels(droplevels(g[g != "c"]))
#> [1] "a" "b"
Source: R documentation: subset
The message of the warning that catches a single = begins with the call and continues on a second line, and its important part is extra argument ‘year’ will be disregarded: year = 2020 is taken as an extra argument and not as a condition, so the whole data frame comes back (16 rows) when the warning is muffled. The output shows the four other effects: the NA row of books[books$year > 2020, ] is not in the subset() result; select with a range and a negative selection; the drop default (subset() keeps a data frame while books[..., "title"] is a character vector, and drop = TRUE gives the vector); and the matrix method, which needs a logical vector (a condition on a column of the matrix, here m[, "p"] > 1) and keeps a matrix by default. [ works with every shape, in every context, and with a computed condition; the price is the repetition of the name of the data frame in every term.
Why not subset() in functions
The warning of the help page is about the evaluation. subset() looks the names in its condition up in the data frame first and then in the environment where it was called, so a name that is both a column and a variable is silently the column. The next script is the classic accident: a helper whose argument has the same name as a column.
source("scenario.R")

# A helper that keeps books longer than a given number of pages. The argument
# is called pages, which is also a column of the data frame.
longer_than <- function(df, pages) {
  subset(df, pages > pages)
}
nrow(longer_than(books, 400))
#> [1] 0

# The condition pages > pages compares the column with itself: the column
# wins, because subset() looks in the data frame first. No row is TRUE, so
# nothing is kept, and no error says why.
longer_than(books, 400)[, c("title", "pages")]
#> [1] title pages
#> <0 rows> (or 0-length row.names)

# With [ the two names cannot be confused
longer_than <- function(df, min_pages) {
  df[which(df$pages > min_pages), , drop = FALSE]
}
longer_than(books, 400)[, c("title", "pages")]
#>                  title pages
#> 2  Pride and Prejudice   432
#> 12    Notes on Gravity   410

# A column name held in a variable cannot be used with $ or inside subset():
# col is a string here, so the condition compares strings with "2020"
col <- "year"
head(books[[col]], 3)
#> [1] 1974 1813 2019
head(books$col, 3)
#> NULL
nrow(subset(books, col > 2020))
#> [1] 16
subset(books, get(col) > 2020)[, c("title", "year")]
#>             title year
#> 4      Loud Roofs 2021
#> 10 THE LONG TABLE 2023
#> 15    Ten Winters 2022

# The usual advice: use subset() at the console, [ in functions and packages.
# A function that needs the NSE can pass the expression on with eval().
newer_than <- function(df, year_min) {
  keep <- eval(substitute(year > year_min), df, parent.frame())
  df[which(keep), , drop = FALSE]
}
newer_than(books, 2020)[, c("title", "year")]
#>             title year
#> 4      Loud Roofs 2021
#> 10 THE LONG TABLE 2023
#> 15    Ten Winters 2022
Source: R documentation: subset
-
longer_than(df, pages)callssubset(df, pages > pages). Bothpagesare the column, because the data frame is searched before the function’s argument, so the condition compares the column with itself and no row isTRUE: an empty data frame, without an error. The[version (df[which(df$pages > min_pages), , drop = FALSE]) cannot have the problem, because the column is alwaysdf$pagesand the argument has another name. -
A column name held in a variable does not work with
$(books$collooks for a column calledcol, and returnsNULL) or with the unquoted names ofsubset(). In the scriptcolis the string"year"andsubset(books, col > 2020)compares the string"year"with"2020"as strings, which isTRUEfor every row: sixteen rows come back and no message says it. Usebooks[[col]]orget(col), the latter inside the data frame as the script shows. -
When a function needs the non-standard form, it can build the condition itself, as
newer_than()does witheval(substitute(...), df, parent.frame()), so that the caller’s argument is evaluated with the columns ofdfvisible. This is what dplyr and other packages automate; the details and their trade-offs are the subject of the evaluation page.
The practical rule is the one the help page gives: subset() for interactive work at the console, [ and [[ in functions, scripts that are run unattended, and packages.
The upcoming R-devel warning for x[logi]
The development version of R (4.7.0, not released) has a change in the NEWS that affects the logical indexes of this page. The R-devel NEWS says that x[logi], with logi a logical index, now warns if length(x) is not a multiple of length(logi), fixing PR#19155, after the discussions of several participants in R Dev Days and the R Sprint in 2026 (R NEWS: Changes in R-devel). The text was read from the development NEWS on 2026-10-20 and the examples of this page were not run on R-devel, so what follows is the consequence and not a captured message.
-
Today, in R 4.6.1, the call
loan_len[c(TRUE, FALSE, FALSE)]with a vector of eight elements is recycled silently and selects the positions 1, 4 and 7; the script of Logical indexes and recycling showswarns()returning no warning. A logical index of length ten for a vector of length eight is also silent (and gives twoNAelements). -
According to the NEWS entry, the same expressions will warn in the development version. Code that relied on a short logical index that does not divide the length (a mask of length 3 recycled over 8 elements, usually by accident) will produce a warning there, and a test suite that turns warnings into errors will fail.
-
A logical index whose length divides
length(x)(x[TRUE], orx[c(TRUE, FALSE)]on a vector of even length) and a logical index of the same length asx, which is the normal case, are multiples in the sense of the rule and are not affected. -
The fix is the same as for any recycling accident: build the mask with the length of the vector (
rep(c(TRUE, FALSE, FALSE), length.out = length(x)), made explicit), or usewhich().
The change is not in any release at the time of the check. Whether it appears under the number 4.7.0 and with this wording is for the NEWS of that release to say; the page What’s New and Migrating Older Code tracks the version differences.
Errors and warnings reference
Every message in the table was produced by an example on this page, by R 4.6.1.
| Message | Cause | Where |
|---|---|---|
|
|
four kinds of index |
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
|
an index that is a list or a function |
unsuitable index |
|
|
|
|
|
|
|
|
matrices, arrays |
|
|
too many subscripts |
|
|
index matrices |
|
|
data frames |
|
|
data frames |
|
|
|
|
|
|
|
|
sub-assignment |
|
|
data frames |
|
|
sub-assignment |
|
|
sub-assignment |
|
|
sub-assignment |
|
|
data frames |
|
|
S4 slots |
Source: R documentation: Extract
Version notes
| Version | What changed for subsetting |
|---|---|
R 2.6.0 |
negative out-of-bounds subscripts are silently ignored, for S compatibility (the language definition) |
R 3.1.1 |
the warning for partial matching with |
R 4.0.0 |
|
R 4.1.3 |
a character matrix index on an array without |
R 4.2.0 |
classed conditions |
R 4.3.0 |
|
R 4.4.0 |
|
R 4.6.0 |
subassignment to a one-dimensional array with a name as the index no longer drops it to a vector |
R-devel (4.7.0) |
|
Where older tutorials differ
| Older tutorial | Current practice | Why | Version |
|---|---|---|---|
|
|
the |
always |
|
|
what is attached is a copy: an assignment to an attached name creates a masking variable in the workspace and the data frame is unchanged, and a change to the data frame is not seen until it is detached and attached again; this reference does not use |
always |
|
|
when nothing matches, |
always |
|
|
a single row or column is silently turned into a vector (R FAQ 7.5) |
always |
|
|
a |
always |
|
the full name, |
|
always; warning option since R 3.1.1 |
the language definition says that |
|
the help page and the behaviour of R 4.6.1 give no partial matching by default |
R 4.6.1 |
An Introduction to R: an index matrix must be numeric, and a character matrix is treated as an indexing vector |
a character matrix with one column per dimension indexes by |
the help page of |
R 4.1.3 |
|
|
non-standard evaluation looks columns up first, so a name that is both a column and an argument is the column |
always (help page warning) |
|
still valid; |
|
R 4.4.0 |
|
|
a factor index uses the integer codes |
R 4.0.0 |
|
vectorised subsetting; |
|
always |
the error message |
|
the text that R 4.6.1 prints; the NEWS files do not record when the wording changed |
R 4.6.1 |
For the full list of changes by release see What’s New and Migrating Older Code.
Where to go next
-
Atomic Vectors and Types for the vectors and the coercion hierarchy that sub-assignment uses.
-
Missing and Special Values for
NA,is.na()and the other special values. -
Lists and Data Frames for building the objects that this page takes apart.
-
Matrices and Arrays for matrix algebra,
apply()over margins and the rest of the array functions. -
Attributes and Names for
names<-,dimnames<-andattr<-. -
Factors for factor indexing,
levels<-anddroplevels(). -
Functions for argument matching and
<<-. -
Evaluation and Non-Standard Evaluation for how
subset(),with()andeval()look their names up. -
Vectorisation and Iteration for avoiding the row-by-row loop.
-
The tidyverse and dplyr and data.table for the add-on packages whose
[and[[follow rules of their own.
References
-
The R Language Definition: Indexing, with Indexing by vectors, Indexing matrices and arrays, Indexing other structures and Subset assignment
-
An Introduction to R: Index vectors; selecting and modifying subsets of a data set
-
An Introduction to R: Array indexing. Subsections of an array
-
An Introduction to R: Index matrices
-
An Introduction to R: Lists
-
An Introduction to R: attach() and detach()
-
R FAQ 7.1: How can I set components of a list to NULL?
-
R FAQ 7.5: Why do my matrices lose dimensions?
-
R FAQ 7.23: How can I sort the rows of a data frame?
-
R NEWS: Changes in R 4.0.0, 4.1.3, 4.2.0, 4.3.0, 4.4.0 and 4.6.0
-
R NEWS (3.x): Changes in R 3.1.1
-
R NEWS (R-devel): Changes in R-devel
-
Extract (
[,[[,$,getElement, and their replacement forms) -
Extract.data.frame (
[.data.frame) -
slotOp (
@)